Repository navigation
feat(dlss): DLSS Frame Generation through NGX, evenly paced at 3x and up - #2118
Conversation


…ge for each frame

Present ahead (NotRexed#1702) submits a paced set's copies into the window together and keeps only the presents on
their times; it ran for 2x only, so at 3x and 4x each made frame's copy still queued behind the game's next
frame on the same queue and reached the screen unevenly (frame generation at 3x felt less even than
Streamline's at the same rates). It now runs for any paced set the swapchain can hold (a spare image per
frame), and the swapchain asks for that many over the surface's least when the menu is at 3x or 4x at the
start (NVIDIA: 5 and 6 images). A set the chain cannot hold is shown one at a time as before.

test_present_ahead.py: 3x and 4x with enough spare images, not with fewer.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…er's depth and motion

Frame generation at 5120x2160 made its frames from the finished picture alone: the block search covers
+-32 px a game frame, so a camera pan's motion fell to zero and every made frame was a cross-fade of the
two game frames (motion stepped at the game's rate). On RTX 40 and newer this makes them with NVIDIA's
DLSS Frame Generation through NGX (no Streamline), from the temporal Upscaler's own depth and motion
(actor motion included) and its camera.

- vk_dlss.cpp: DLSS-G beside DLSS, on the same NGX session. The chain's depth and motion are copied at its
  evaluation (dlss_fg_inputs) with the camera (the scene's projection is now kept beside its view-projection,
  camera block 0x70); at the present the made frames of the Frame generation row's set are evaluated into
  the renderer's own set (dlss_fg_frames), which the display thread shows and paces as before. A set it
  does not make (no Upscaler this frame, a gap, more frames than the GPU makes, a refusal) is made by the
  renderer's own methods as before, and the log counts which and why every 600 presents.
- The motion goes to NGX in render pixels (MvecScale 1), as to DLSS. With 1 / render size (the [-1, 1]
  nvsdk_ngx_defs_dlssg.h describes, which is Streamline's convention) DLSS-G saw no motion and every made
  frame was a cross-fade again: captured at 5120x2160, t = 1/3 and 2/3 and 0.2 of 255 off a pure blend;
  with 1 the same scenes came out as moved pictures between the game's.
- Insert menu: a "Frame generation by" row, Auto (DLSS-G where it runs, else the built-in one) or
  Built-in, and the Frame generation and Frame pacing rows moved under the Upscaler's (asked for in #dev-work). Its device
  extensions are asked of NGX whenever DLSS may run and the chain's images are always copyable, so the row
  changes at once; turned off, the feature is let go. RX_VK_DLSS_FG=0 / 1 over the row for a run.
- At the exit the feature is let go with the queue idle (as PR 1944's Streamline path needed).
- nvngx_dlssg.dll is looked for where DLSS's runtime is (the game folder's ngx first).

Played on an RTX 5090 (driver 621.14, Windows 11), 5120x2160 DLAA, frame generation 3x: DLSS-G made every
set in gameplay (600 / 600), ~135 frames shown from ~45 game fps; clean exits.

Tests: present_source_crop_test.cpp stubs dlss_fg_wanted / dlss_fg_frames; test_recorder_sync.py knows
NGX's frame generation calls (NGX_VK_*_DLSSG) as recordings with their B_DIRECT boundary;
test_upscaler_rows.py checks the new order (frame generation between the Render resolution and the window
rows).

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
With V-Sync Auto the swapchain is mailbox where the driver has it: NVIDIA's Fast Sync, which puts frames on
the refresh grid whenever they come slower than the display. With frame generation at 3x (~135 shown on a
165 Hz screen) the display thread's evenly timed presents still reached the screen unevenly. Auto now asks
for FIFO when frame generation is at 2x and up, which a VRR display shows as presented; On and Off are as
before. The swapchain is made again when frame generation's multiplier changes, as for V-Sync itself
(swapchain_framegen), so its present mode and its spare images (present ahead) follow the row.

Tests: test_vsync_row.py's present-mode choice with frame generation (Auto FIFO with or without mailbox,
On and Off as before); test_present_semaphores.py stubs swapchain_framegen.

Played on an RTX 5090, 165 Hz G-SYNC, 5120x2160, DLSS Frame Generation 3x: even pacing (as with Streamline's
DLSS-G in NotRexed#1944), and the game ~45 fps instead of ~42.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>


|
Tested exact head ec27f1f on an RTX 5070 Ti / Windows 11, 3440x1440 output, DLSS Quality 2294x960, game cap 60, FG 2x, pacing on. Fresh guest generation and matching API 14 host/backend build. NGX loaded the pinned official SR runtime and the DLSS-G runtime supplied with Streamline 2.14.16 from an isolated ngx directory; no Streamline interposer was loaded for this path. NGX created its feature and logged repeated 600/600 sets made by DLSS-G, with zero refused and no fallback in those windows. Three controls used the same host/backend, copied checkpoint and active window. The controller reported 3440x1440 at 159 Hz; all three swapchains logged FIFO (V-Sync Auto). PresentMon 2.6 recorded actual display timestamps, separately from the native-present trace; no pixel capture during timing.
Native rates stayed around 60 in all modes. Displayed P95 in the first return second: 18.78 ms off, 12.51 ms built-in, 12.52 ms NGX. There was no missing display feedback in those measurement windows. Normal exit from inventory returned 0 with NGX active, and both controls also exited normally. Presented hearts/instructions and inventory text were legible in the frames inspected after timing. This confirms the NGX path runs on this RTX 50 setup. It is one run per mode in the initial interior scene, not a latency, motion-quality, 3x/4x, fixed-refresh, or campaign test. With the game capped at 60, both FG methods reach about 120 displayed/s here; these measurements do not establish an overall winner. PresentMon marked frames Application, so individual generated-frame identity comes from neither that label nor the UI screenshots; the generator attribution above comes from the NGX set log. |

|
I tested this on an RTX 5080 (1920x1080 at 360 Hz, G-SYNC, driver V-Sync on, in-game V-Sync Off) at 4x, measuring input latency with DLSS-G against frame generation off. DLSS-G worked well: it made every set in gameplay ("600 made by DLSS-G" in each window). It adds a fair amount of latency, though, and part of that is because NVIDIA Reflex is off while it runs. How I measured. The game pressed its own buttons through
These are medians. The 10–90% range was about ±5 ms around each, and the two modes don't overlap. The game's own frame rate was about 77 fps with DLSS-G and about 99 fps with frame generation off. Reflex is off whenever frame generation is on, DLSS-G included.
The frame-generation-off run had Reflex On + Boost and the DLSS-G run had none, so the gap above includes both frame generation's held-back frame and Reflex's pacing. NVIDIA's own integrations (Streamline) require Reflex while DLSS-G is on, to win back exactly this latency, so it seems worth having here too. A possible fix. As far as I can tell, Reflex is off under frame generation because its per-frame calls assume one present per game frame. Its calls fall into two groups, and only the second actually conflicts:
So
|
…d, made frames without present ids

Reflex was off whenever frame generation was on (on() required !framegen_on()), so its held-back frame
added its whole delay: on an RTX 5080 at 4x DLSS-G measured +12 to +18 ms from input to the screen against
frame generation off with Reflex on (PR 2118's review, breakthetargets, who also laid out this split).
NVIDIA's own integrations keep Reflex on with DLSS-G for this reason.

The calls that describe the game's frame stay on with frame generation: the latency sleep, the simulation
and input markers after it, the simulation end and submission start at do_present, and the submission's end
(reflex_game_submitted, once the set's recording is submitted). The present calls run in the present path
the display thread also uses for made frames, so they now know which frame a present shows:
- framegen_record keeps the game frame the set was made at (reflex_frame) with the set;
- the display thread sets reflex_present_frame per present: the set's game frame gets that frame's present
  id and its PRESENT_START/END markers, made frames get neither (a deferred present keeps it in its
  PendingPresent until present_commit);
- present ids only go up: one that would not (frame generation turned on or off with sets in flight) is
  left off; a new swapchain starts again;
- the display thread's copies are not the game's render submission.
Without frame generation nothing changes: reflex_present_frame is kReflexThisFrame, the frame being made.
The NVIDIA Reflex row's help says it now works with frame generation.

Tests: test_reflex_swapchain_lifetime.py: a wait that turns frame generation on still marks the frame; with
frame generation the game frame's markers, a made frame without present id or markers, the set's game frame
with its own id, an id that does not go up left off. present_source_crop_test.cpp stubs reflex_frame.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
|
Thanks @Arkex-ai for the 5070 Ti run, and @breakthetargets for the latency numbers and the Reflex write-up. I pushed your split as a new commit here (
On the 5090 (5120x2160, DLAA, Reflex On + Boost, same spot), Reflex's own timings (
That's Reflex's view, so it can't show what turning Reflex on under frame generation wins back: with Reflex off there's no timing to compare against. @breakthetargets, could you rerun your input-to-screen measurement on the new head? That's the comparison that counts. Most of the remaining gap is the interpolation itself: the real frame is shown after its set's made frames, about ⅔ of a game frame later at 3x. |
|
Thanks for the quick follow-up. I reran the same test on 3a39e3f, with the same PC, settings, spot and method as my comment above. This time Reflex now runs with DLSS-G. The DLSS-G run wrote 59 Reflex timing reports while DLSS-G made every set. Before this commit it wrote none.
These are medians of 20 presses each. The walk gap shrank by about 5 ms and the sword gap by about 2 ms, but part of that may be run-to-run noise. Overall, the latency barely changed. Reflex's own timings show why:
So the change looks right. It should pay off in GPU-bound scenes, where frames do queue up: higher resolution, heavier settings or a slower card. One thing looks off: the GPU-end timing with frame generation. With frame generation on, Reflex's "to the GPU's end" reads 243–442 ms, next to about 21 ms from simulation start to present end. With frame generation off it reads a sensible 12.1 ms. It looks like the driver is pinning the GPU's end of a frame on later work. A possible fix (untested, just a direction). Hookshot never chains
If this is the cause, |

 hckrman101
left a comment
hckrman101
left a comment
There was a problem hiding this comment.
Thanks for this. It's focused, it builds alone, CI is green, and it has been tested on three RTX 50 cards (Arkex-ai's 5070 Ti run, nullifyshot's latency numbers, and the Reflex follow-up you added after them).
Overlap: #1831 adds the same feature (DLSS-G through NGX, on DLSS's session). Only one of them should land, so the two need to converge. Your description already says you're open to folding this into either.
Compared against #1831's diff, this PR:
- feeds DLSS-G the temporal chain's motion, actor motion included. #1831 uses FSR 3.1's assembled inputs, which have camera motion only.
- reads
MultiFrameCountMaxand leaves sets it can't make to the built-in method. #1831 hard-codes 3 made frames and quietly makes a 4x set at 5x to 8x. - waits for the queue to go idle before releasing the feature and defers freeing its images. #1831 releases both straight away on a resize.
- presents 3x/4x sets ahead and keeps Reflex on under frame generation. Neither is in #1831.
- builds alone at about an eighth of the size. #1831 needs #1833 and #1834.
What #1831 does better, and could be adopted here:
- Its DLSS-G doesn't need a temporal upscaler. Its inputs are made at the gameplay upscale "whatever upscales" (its own comment), so it isn't tied to the Upscaler row. Here it needs a temporal Upscaler on.
- Its method choice is a small pure header (
framegen_methods.h) with a unit test. The newFrame generation byrow here has no test of its own beyond the row order. - It asks NGX for frame generation's device extensions only when frame generation is wanted (see the inline note on gating).
- Its single/pair/no-weight actor-motion layouts. You suggested those as their own PR, and I agree.
Inline notes below. Still open from the thread: nullifyshot saw Reflex's "to the GPU's end" read 243 to 442 ms with frame generation on, and suggested tagging submits with VkLatencySubmissionPresentIdNV. That's fine as a follow-up, but please say so in the description so it isn't lost.
The decision on which of the two lands stays with @NotRexed.
|
|
||
| bool dlss_fg_wanted() { return fg_asked(); } | ||
|
|
||
| void dlss_fg_device_extensions(std::vector<const char*>& want, const std::vector<VkExtensionProperties>& all) { |
There was a problem hiding this comment.
This calls NVSDK_NGX_VULKAN_GetFeatureDeviceExtensionRequirements at every device creation in a DLSS build, on AMD and Intel GPUs too and with frame generation off. Main's dlss_device_extensions and dlss_probe avoid NGX unless the device has the NVX extensions (DLSS_NEEDS_RTX). Could this get the same gate, i.e. skip when VK_NVX_binary_import/VK_NVX_image_view_handle aren't in all? fg_start could also return early when dlss_why() says the device isn't NVIDIA's, so the first 2x present on an AMD card doesn't run ngx_init.
There was a problem hiding this comment.
Done in 90c4683 (fix(dlss): DLSS-G only where it runs). dlss_fg_device_extensions now returns before NGX when the device lacks VK_NVX_binary_import or VK_NVX_image_view_handle, the same check as dlss_device_extensions. fg_start returns before ngx_init when dlss_why() isn't DLSS_OK, so the first 2x present on an AMD card doesn't start NGX. On an NVIDIA device NGX is still asked with frame generation off, so the Frame generation by row works without a restart.
There was a problem hiding this comment.
Confirmed in 90c4683, thanks: both the extension query and fg_start are now gated.
| // (hookshot) V-Sync Auto with frame generation at 2x and up: FIFO. Mailbox, NVIDIA's Fast Sync, puts the made frames on the | ||
| // refresh grid whenever they come slower than the display (DLSS Frame Gen 3x: ~135 shown on a 165 Hz screen), so evenly | ||
| // timed presents still reached the screen unevenly; FIFO on a VRR display shows each one when it is presented | ||
| const bool fg_fifo = vsync == 0 && swapchain_framegen() >= 2; |
There was a problem hiding this comment.
This changes V-Sync Auto for every GPU and for the built-in frame generation too, not only DLSS-G. On Windows it also skips the immediate fallback that the comment below keeps for AMD ("FIFO held anything under 60 fps at 30"). The description lists fixed-refresh displays as untested. Could this be limited to where it was measured (DLSS-G running, or at least NVIDIA), or else tested at 2x on a fixed-refresh/AMD setup?
There was a problem hiding this comment.
Limited to DLSS-G, where it was measured (90c4683). swapchain_dlssg() is true only at a fixed multiplier with DLSS-G asked for, on a device it runs on, and NGX not having said no. The built-in frame generation and other GPUs keep Auto as on main, including the Windows immediate fallback for AMD. The swapchain is made again when that changes. test_vsync_row now covers both cases. A fixed-refresh display is still untested, as the description says.
There was a problem hiding this comment.
Confirmed: FIFO is now for DLSS-G only, and the built-in method and AMD keep main's Auto. Thanks.
| static int told = 0; | ||
| if (told++ < 8) logf("vk: DLSS Frame Gen (NGX): frame %d of %d was refused (%#x)", k, count, (unsigned)r); | ||
| g.last_sequence = 0; | ||
| return g.refused++, 0; // (a half-made set: the renderer's own makes all of it) |
There was a problem hiding this comment.
Nit: when frame k>1 is refused, frames 1..k-1 have already been written by NGX into out[], and the built-in passes then write the same images in the same command buffer. No barrier is recorded on this path, so that's a write-after-write without a dependency. A fg_barrier(cmd) before returning would cover it.
There was a problem hiding this comment.
Fixed in 90c4683: fg_barrier(cmd) before returning when frame k > 1 is refused.
| // (hookshot) NVIDIA DLSS Frame Generation through NGX where it runs and the Frame generation by row asks for it (vk_dlss.cpp): | ||
| // every made frame of the set, from the scene's own depth, motion and camera. A set it does not make goes on below as before | ||
| // (asked every present: turned off, it lets its feature go) | ||
| if (m > 1) { |
There was a problem hiding this comment.
Nit: the feature is only let go when the Frame generation by row changes. With Frame generation set to Off or Auto, dlss_fg_frames isn't called anymore (m > 1), so DLSS-G's feature (large at 5K) stays allocated for the rest of the run. Releasing it when the multiplier drops below 2 would match the row's "changes at once".
There was a problem hiding this comment.
Fixed in 90c4683: dlss_fg_idle() runs at each present without a fixed multiplier (Off or Auto) and lets the feature go if one is held. When there's nothing to release it's one atomic load.

…let go at Off or Auto

From the review:
- NGX is not asked for frame generation's device extensions on a device
  without NVIDIA's NVX extensions (AMD, Intel), and fg_start does not start
  NGX where dlss_why() says DLSS does not run.
- V-Sync Auto's FIFO under frame generation is limited to DLSS-G making the
  sets (swapchain_dlssg), where it was measured; the renderer's own methods
  and other GPUs keep Auto's mailbox or immediate. The swapchain is made
  again when that changes.
- A frame NGX refuses after the first: a barrier before the renderer's own
  passes write the same images.
- Frame generation at Off or Auto lets DLSS-G's feature go (dlss_fg_idle),
  as a change of the Frame generation by row does.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
|
Thanks for the review. The four inline points are fixed in a new commit, 90c4683 From #1831's side:
Agreed that the choice between this and #1831 is @NotRexed's. |
…-ngx

# Conflicts:
#	gpu/vk/vk_replay.cpp
hckrman101
left a comment
hckrman101
left a comment
There was a problem hiding this comment.
Thanks, re-reviewed at fb09afc (90c4683 plus a merge of main).
All four earlier points are fixed:
- NGX isn't asked for frame generation's device extensions without
VK_NVX_binary_import/VK_NVX_image_view_handle, andfg_startstops beforengx_initwhendlss_why()isn'tDLSS_OK. - V-Sync Auto's FIFO is now for DLSS-G only (
swapchain_dlssg()), so the built-in frame generation and AMD keep main's behaviour, including the Windows immediate fallback.test_vsync_rowcovers both cases, and the swapchain is rebuilt when it flips. - A refused frame k > 1 now gets
fg_barrier(cmd)before the built-in passes write the same images. dlss_fg_idle()lets the feature go at Off/Auto. It runs on the presentation thread, wheredlss_fg_framesalso runs, and takesg.muthenpresent_muin the same order, so I don't see a lock-order problem.
The Reflex submit tagging (VkLatencySubmissionPresentIdNV, nullifyshot's GPU-end reading) is now in the description as a follow-up, which is what I asked for.
One nit, inline: after three failed feature creations, dlss_fg_runs() still says yes, so V-Sync Auto stays FIFO while the built-in method makes the sets. That's an edge case and doesn't block.
From #1831, worth adopting. #1831 is being closed in favour of this PR. These are FIocker's ideas, and none of them blocks this one. They would be good follow-ups, with credit:
- DLSS-G without a temporal upscaler. #1831 makes camera-only motion from depth (
vk_camera_motion), so its DLSS-G runs with the Upscaler off. Here DLSS-G needs DLSS, DLAA or FSR. You've said this could be a follow-up, and that's fine. - The method choice as a small pure header with a unit test (
framegen_methods.h). In #1831, an unknown saved value reads as Auto, and the row only offers methods that run on this PC. Here, a saved out-of-range value clamps to Built-in, and an AMD card sees Auto and Built-in, which do the same thing. You offered to do this, and I'd take it, here or in the follow-up. - Actor motion. This PR is already ahead of #1831 here: its DLSS-G gets the chain's actor motion, while #1831's gets camera motion only. What #1831 adds is wider skinning coverage in
dlss_actor.vert/bones_used(the single, pair and no-weight layouts: Link's shield and hair, rigid props). That helps DLSS and DLSS-G alike, and you plan it as its own PR. - Already done, nothing to adopt: sharing DLSS's NGX session (this PR does it too) and asking for NGX's frame generation extensions only on NVIDIA devices (90c4683).
CI on fb09afc was still queued when I reviewed, so please merge once it's green. Approving.
|
|
||
| bool dlss_fg_wanted() { return fg_asked(); } | ||
|
|
||
| bool dlss_fg_runs() { return fg_asked() && dlss_why() == DLSS_OK && !fgs().start_failed.load(std::memory_order_relaxed); } |
There was a problem hiding this comment.
Nit: after create_failures >= 3, dlss_fg_frames refuses every set, but this still returns true, so V-Sync Auto stays FIFO while the built-in method makes the sets. Setting start_failed (or a separate flag) once creation gives up would hand Auto back to main's mode.
…-ngx

# Conflicts:
#	gpu/vk/vk_menu.cpp
…back to its mode

From review: after create_failures >= 3 dlss_fg_frames refuses every set,
but dlss_fg_runs still said yes, so V-Sync Auto stayed FIFO while the
built-in method made the sets. Giving up now sets start_failed, which
dlss_fg_runs reads; present_image makes the swapchain again.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
|
Thanks for the approval. Main is merged in again (#2042 touched the Reflex row), and the nit is fixed in 7c13821. I'll take the method choice as a small header with a unit test in the follow-up, together with DLSS-G without a temporal upscaler, and the single/pair/no-weight actor-motion layouts as their own PR, with credit to FIocker. |
…-ngx

# Conflicts:
#	gpu/vk/vk_framegen.h
#	gpu/vk/vk_internal.h
#	gpu/vk/vk_main.cpp
#	gpu/vk/vk_replay.cpp
hckrman101
left a comment
hckrman101
left a comment
There was a problem hiding this comment.
Re-checked at fd6aaa5. The only code change since my approval is 7c13821 (the rest are main merges). Setting start_failed once creation gives up at three failures makes dlss_fg_runs() say no, so V-Sync Auto goes back to its normal mode. That's what my nit asked for, and it matches the existing "off" log line (it was already permanent after three failures). Thanks for taking the #1831 ideas on as follow-ups.
CI is still running on this head after the main merges (#2042 touched the Reflex row), so it's worth waiting for green before merging.


NotRexed#2118's DLSS Frame Generation (NGX) copies the chain's depth each frame and
told NGX it was not reversed. With FSR 3.1 on the chain the depth is 1 - d
(dlss_prep.comp bit 3), so generated frames under FSR 3.1 would have had
their occlusion backwards. The frame's depth_reversed now goes with the
copied inputs (Fg::depth_reversed) and into
NVSDK_NGX_DLSSG_Opt_Eval_Params::depthInverted. DLSS and FSR 4 are
unchanged (their depth is not reversed).

test_upscaler_rows checks both lines; it fails with the hard-coded false.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

…ters' motion (#2305) AMD FSR 3.1 makes its own inputs (`vk_fsr3_inputs.cpp`), and the only motion it gets is the camera's. So anything that moves differently from the camera is given the motion of what's behind it: Link while he walks, his swinging arm, his shield, and the people around him. DLSS and FSR 4 already get those characters' own motion on `vk_temporal.cpp`'s chain. This PR puts FSR 3.1 on that chain too, as a third engine, so all three temporal upscalers share the same inputs. **What changed** - `vk_fsr3.cpp/.h`: `kChainEngine`, FSR 3.1 as a `TemporalEngine` (slot 2). - It takes the chain's colour, depth, motion (with the actor pass drawn over it), jitter and jitter phase count. - It builds FSR's depth constants from the unjittered projection. - Its picture is copied into the chain's output and squared back by `dlss_out.comp` as before. - `fsr3_chosen()` is "the row or `RX_VK_FSR=1` picks FSR 3.1". `fsr3_wanted()` now means "FSR 3.1 on its own inputs", which is false while it's on the chain. - `fsr3::prepare_sizes` and `fsr3::release` let the chain size and free FSR's images. - `vk_temporal.cpp/.h`: - `temporal_mode` returns `FSR3` for the row's FSR 3.1 before it falls back to the game's own; `engine_of` gets a third slot. - Two new `TemporalEngine` fields: - `fsr_depth`: the chain reverses depth for FSR's passes (built with `INVERTED_DEPTH`) where the projection puts the near plane at 0. - `retry`: a failed evaluation hands that frame to the network instead of turning the engine off for good. FSR 3.1's constants come from the frame's stream, which can run out for one frame. - `TemporalFrame` carries the unjittered projection and the jitter phase count. - The chain's output image gets `TRANSFER_DST`. - `RX_VK_FSR_JITTER=0` still turns FSR 3.1's jitter off on the chain. - `shaders/dlss_prep.comp`: - Flag bit 3 reverses depth (`1 - d`). - A NaN in the scene colour is written as black, following `fsr3_prep.comp`'s rule, because one NaN spreads through an upscaler's history. - The header was regenerated with `glslangValidator -V --target-env vulkan1.3 --vn DLSS_PREP_COMP_SPV`, the command `test_dlss_actor.py` checks. - `RX_VK_FSR3_CHAIN=0` gives FSR 3.1 its own inputs, as before, for comparisons (`docs/development.md`). The readme's FSR 3.1 section describes the new inputs, and says what still trails: things that aren't skinned, such as Navi's body. - Tests: - `temporal_jitter_test.cpp` covers FSR 3.1's slot and its failure gate, and a new run (`fsr-jitter-off`) where only `RX_VK_FSR_JITTER=0` is set: FSR 3.1 on the chain gets no jitter, and DLSS and FSR 4 keep theirs. - `test_upscaler_rows.py` checks that the row's FSR 3.1 runs on the chain before the fallback to the game's own, that `fsr3_wanted` is off while it does, and that `engine_of` has its slot. - Both fail on main. A mutated jitter gate fails `fsr-jitter-off`. **Testing** - `python -I -B tests/run_all.py`: 363 passed, 0 failed, 11 skipped (Linux; the skips are Windows-only, need a Vulkan 1.3 device, or need dotnet). - In game: RX 9070 XT 16 GB, Mesa RADV 26.2.6, Gentoo Linux (kernel 7.3.3), KDE Plasma Wayland, windowed, 2560x1440 output, 60 fps cap. - Host v2.1.0-main-local (source fc2ed0d0). Renderer: main 49f75dc plus this branch. - "Own" means the same build with `RX_VK_FSR3_CHAIN=0`, which is what main does. - Every chain run logged `vk: fsr3 on the chain: 600 frames drawn ... depth reversed for FSR by the chain`, with no evaluation failures. | FSR 3.1 | Kokiri Forest, 28 s camera turn (4 runs each) | Castle Town market at noon (3 runs each) | |---|---|---| | Own inputs (as main) | 59.2 fps, 1% low 46.4 | 53.1 fps | | On the chain | 59.3 fps, 1% low 48.1 | 52.5 fps | Market runs vary by about 0.9 fps between runs, so the chain costs nothing measurable. - Picture: consecutive 2560x1440 shots at Kokiri's lost-woods path, standing and walking, compared on the same build. Edge flicker is the mean frame-to-frame change of edge pixels, 0-255, while standing. | FSR 3.1 | Edge flicker, standing | 1-px outlines per MP | Halos per MP | |---|---|---|---| | 100%, own | 2.17 | 32 | 45 | | 100%, chain | 2.20 | 29 | 50 | | Quality (67%), own | 3.01 | 12 | 25 | | Quality (67%), chain | 1.67 | 2 | 9 | Four independent reviewers of the walking sheets saw no visible difference at 100%. At 67%, they found the chain slightly better: smoother edges on Link's shield and tunic hem, and slightly softer shield texture. No new artefacts. The clearest evidence is the motion field itself (below). On main, Link isn't in it at all. **Not tested:** - other GPUs and drivers; - Windows; - Steam Deck, where #2110 would make FSR 3.1 the default; - frame interpolation (`RX_VK_FSR_FG=1`), which keeps using `vk_fsr3_inputs.cpp`; - switching upscalers repeatedly while playing (release and remake are code-reviewed, not exercised in game); - HDR: the chain still clamps FSR 3.1's colour at the paper white, as main does (see below). **Screenshots** (from the game's output image before the present path, 2560x1440) The motion vectors the upscaler gets while Link walks (`RX_VK_DLSS_DEBUG=motion`). Left: camera motion only (`RX_VK_DLSS_ACTORS=0`, which is what FSR 3.1 got on main). Right: on the chain, with Link's body, arm and shield carrying their own motion: 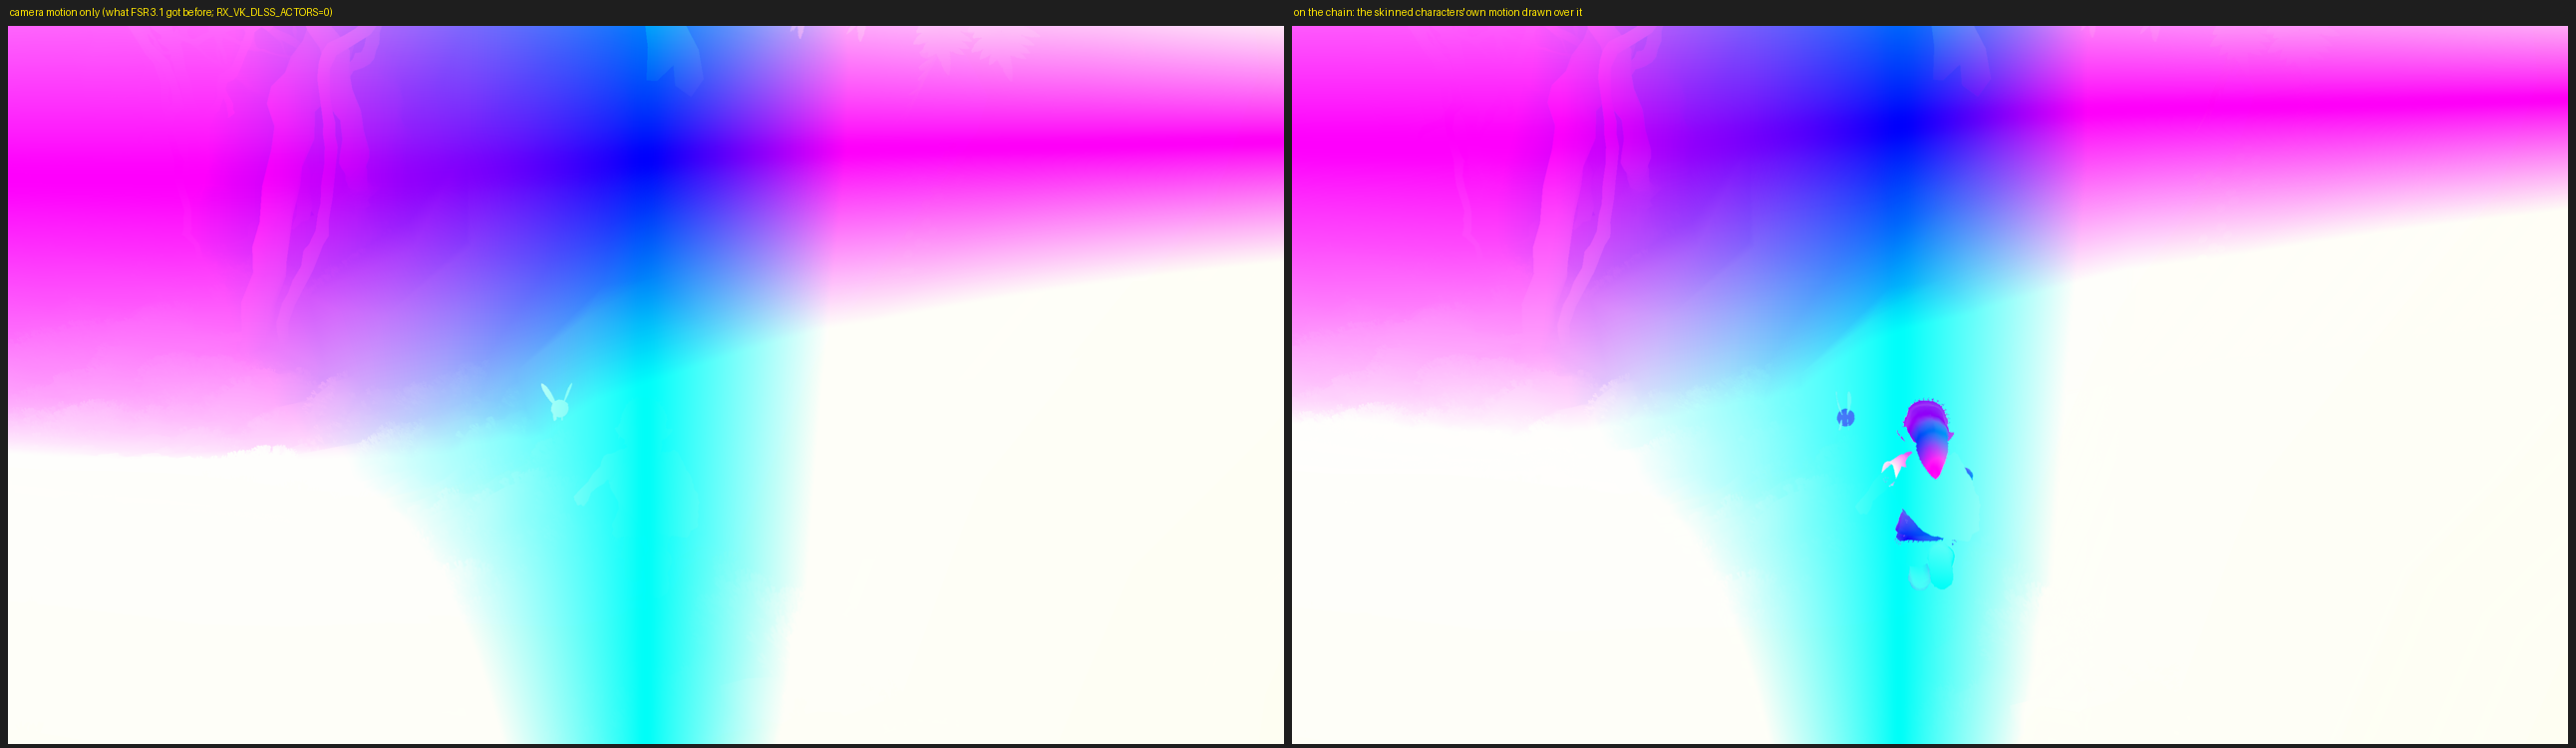 Link walking: own inputs vs the chain, at 100% and at 67% (2x zoom crops): 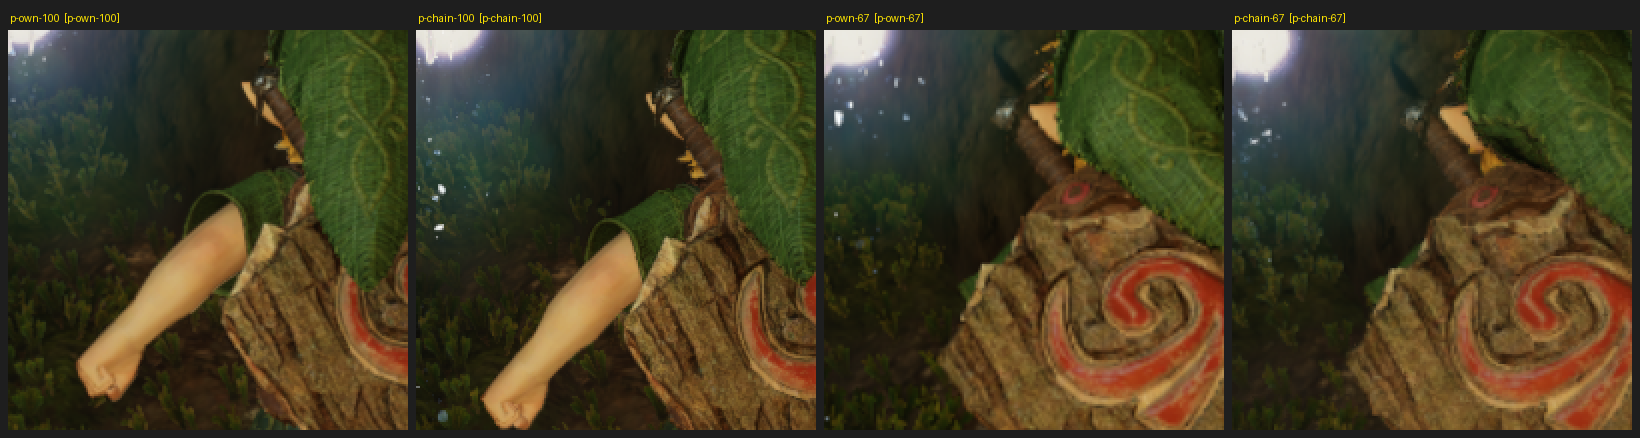 **Merge notes** (from test merges against every open PR that touches these files; textual conflicts show up in git, semantic ones don't) - **Depth is reversed for FSR 3.1 on the chain.** `TemporalFrame::depth_reversed` says so. Anything that reads the chain's depth must check it rather than assume plain depth: - #2118 (DLSS frame generation through NGX, now on main): done in this PR. Commit ca2e302 passes `depth_reversed` to NGX's `depthInverted`, and `test_upscaler_rows` checks it. - #1944 (DLSS frame generation through Streamline) needs the same: `depthInverted` from `depth_reversed`, not a hard-coded false. - #1831/#1833: `nr_pre` passes `s.depth` on, and the NGX backend's `DepthInverted` should follow it too. - **#2145** adds `bool native_aa` to `TemporalEngine::prepare`. `chain_prepare` in `vk_fsr3.cpp` needs the same parameter, or the build breaks. git merges the two cleanly. FSR 3.1 never has native AA. - **#1653** (reactive mask) is on main now and merged into this branch. Commit 7ceae45 makes the mask in `chain_evaluate` the same way DLSS does on the chain, and `test_reactive_mask.py` checks it. Checked in game with `RX_VK_REACTIVE=1`: the mask is made, and FSR 3.1 draws all 600 frames on the chain. - **#2243** (DLSS HDR, linear light) is on main now (in #2342's squash, a0dfd28) and is merged into this branch. - `dlss_prep.comp` scrubs NaN first, then applies #2243's `max`/`kSquare`/`min`, and keeps the `flags & 8` depth flip. The header was regenerated; glslang 16.4.0 gives the same SPIR-V words as CI's 16.6.0 for `dlss_prep` and `dlss_out`. - `TemporalEngine` is ordered `memory`, `hdr`, `fsr_depth`, `retry`: DLSS's and FSR 4's engines are positional, and `kChainEngine` is designated. - FSR 3.1 doesn't report `hdr` yet, so it keeps the LDR pair. Giving it HDR colour on #2243's mechanism is a follow-up. - **#1831**: - It reads `fsr3_wanted()` to ask whether FSR 3.1 is chosen. After this PR that question is `fsr3_chosen()`. Its `fsr4 = !fsr3_wanted() && fsr4_wanted()` guard and its jitter guard should use `fsr3_chosen()`. The merge is textually clean, so git won't flag it. - In `vk_temporal.cpp`, the output image's usage should become `TRANSFER_DST | TRANSFER_SRC`, and its `proj[16]` and this PR's `projection[16]` should become one field. - **#2166** only matters with `RX_VK_FSR3_CHAIN=0`. - `docs/tested-configurations.md` and `docs/development.md`: rows next to other PRs' rows; keep both. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>

… the fork's side

Upstream's 73 commits since the last merge, with its NVIDIA DLSS Frame
Generation through NGX, taken as it is: the fork's own vk_dlssg.cpp and
dlssg_math.h are gone. Upstream measured in the game that NGX takes motion
in render pixels, which the fork's version had wrong from the headers.

Frame generation: upstream's Frame generation by row (Auto, Built-in)
keeps its key and values, and the fork adds AMD FSR 4 (vk_ffx.cpp) and
AMD FSR 3.1 after them where they run. Neither is ever Auto's: both are
given the picture with the HUD in it. A set a method does not make whole
is the renderer's own.

Neural rendering: runs once for each of the game's frames, before frame
generation, on the picture's part of the window image alone (it was run
over all 2560x1440 of a 2048x1152 picture), and is left out of a native
HDR picture. Two rows the RenoDX DLSS add-on has are new: Passes (1 to
10, a feature or a Streamline viewport a pass, local tone on the first
alone) and Resolution scale (50 to 100%: the model on a smaller copy,
its detail added back at full size, shaders/nr_detail.comp).

Every fork backend that hands the command buffer to someone else's code
goes through the recorder (B_DIRECT before, note_work after), and
tests/test_recorder_sync.py checks each with a control.

Run in the game on an RTX 5060 Ti, Linux (docs/upscaling.md): each
upscaler that exists there, DLSS Frame Generation at 2x to 4x, Built-in,
AMD FSR 3.1's interpolation, and the open neural rendering network with
and without frame generation and at 50% scale. Windows-only code (AMD
FSR 4, Streamline) and NVIDIA's neural rendering model, which has no
Linux runtime, are compiled for Windows and not run.

Tests: 413 passed, 12 skipped (Windows-only or missing tools).

Co-Authored-By: Claude Fable 5.2 <noreply@anthropic.com>
The Graphics tab is one list of 24 settings, with the window, HDR, upscaling, frame generation and GPU options mixed together, and about ten more are on their way in open PRs. This puts its rows under section titles, so the upscaler, frame generation or HDR can be found without scrolling the whole list. It is the first step of a menu organization laid out below for discussion. **What changed** - The Graphics rows in six sections, under heading rows like the Debug tab's Developer (a gold title, never selected, nothing to click): - Quality preset (first: it sets rows in every section) - **Resolution and upscaling:** Output resolution, Profile, Upscaler, DLSS model, Render resolution, Sharpness - **Frame generation and latency:** Frame generation, Frame pacing, Game frame rate cap, NVIDIA Reflex, AMD Anti-Lag 2 - **Screen:** Fullscreen, V-Sync, Window scaling filter, Aspect ratio (#2119), Ultrawide menus - **HDR:** HDR, HDR paper white, HDR peak brightness, HDR contrast (#2342), HDR tone mapper (#2481) - **Detail:** Anisotropic filtering - **GPU and memory:** GPU device, VRAM budget (#1859), Mesh shaders (Robust buffers is on Debug ▸ Developer since #2042) - Moves only: every row's definition is unchanged, word for word; no row is renamed and no value or saved key changes, so options files carry over, and #1864's tables (keyed by the English text) still find every row. They need the six headings. - No new drawing or input code: the menu already draws heading rows on any tab, and the keys, the pad and the mouse step over them. - `readme.md`: a sentence on the sections, and the option table in the new order. (Ultrawide menus and Mesh shaders have no line yet; #2105 adds them.) The **Frame generation by** row from #2118 gets its line in the table here too: main's readme has none yet. So do #1859's **VRAM budget** (under GPU and memory) and #2342's **HDR contrast** (under HDR). - `tests/test_upscaler_rows.py`: its order list follows the picture's path (output, upscaler, render size, sharpening, then the frame rows, then the window). New `tests/test_menu_sections.py`: the Graphics sections and which rows they hold, and on every tab no section that `row_shown` could leave empty (a title over nothing on a GPU without Reflex, say). **The plan this is step 1 of (for discussion)** Each tab answers one question; a section groups the rows you set together; a row that depends on another follows it; vendor rows sit beside their counterpart and hide where they can't run (no vendor sections, so nothing is left empty on AMD); rows to touch only when something is wrong go last; moves only, no renames. | Tab | Holds | Sections | |---|---|---| | **Game** (was Gameplay; first, where the menu opens) | how the game behaves and reads, and Restart and Quit, as a pause menu | flat; Restart and Quit last | | Graphics | how the picture is made, and what it costs | Quality preset · Resolution and upscaling · Frame generation and latency · Detail · GPU and memory | | **Display** (new) | how it gets to your screen, and what is drawn over it | Screen · HDR · Overlays (FPS counter, Menu size, from Game) | | Audio | sound out and in | + Microphone (from Game: it picks the input device) | | Controls | how you play | Camera · Controller · Buttons (optional) | | Debug | tools and developer switches | Robust buffers in Developer (#2042, merged) | Next PRs, one topic each: (2) a Display tab, taking the Screen and HDR sections over whole and adding Overlays; (3) the Gameplay tab titled Game, first in the strip, where the menu opens; (4) Microphone to Audio; (5) optional, sections on Controls. If a sixth tab is a no, this PR stands on its own. Open questions: 1. A sixth tab (Display)? 2. V-Sync on Display (the PC convention) or with frame generation (it changes with it)? 3. Sharpness with the upscaling rows (where players look for it) or with the window filter (where it runs)? 4. DLSS 5 (#1590) and #1834's Neural rows as a page opened from a Graphics row, like Motion, rather than a seventh tab? <details><summary>Where open PRs' rows would go</summary> - Resolution and upscaling: Sharpening method (#1979), DLSS 5 page (#1590), Native 3D resolution (#2017) - Frame generation and latency: Frame generation by (#2118, merged: in this section now), Frame generation method (#1834) - Detail: Shadow resolution (#1892), Screen filter and Filter strength (#1488) - GPU and memory: Texture streaming cache (#2017), Refresh memory (#888); VRAM budget (#1859, merged) is in this section now - Game (was Gameplay): Game language and Menu language (#1864), Skip title screen (#1560), Amiibo (#1521) - Controls: Camera speed (#1945) - #2042 (merged) moved Robust buffers to Debug ▸ Developer. - #2105: its readme check would read the heading rows as rows; it needs to skip `{TAB_..., "...", nullptr, 0, 0, 0, ..., true}` headings, or this PR adds that if it lands first. Whichever PR lands second moves one row on rebase; happy to do it for anyone. </details> **Testing** - `tests/run_all.py` on Windows 11 (llvm-mingw clang, 8 at once) after merging main at 2dfe901 (with #2119's Aspect ratio, #2481's HDR tone mapper, #2118's Frame generation by, #2342's HDR contrast and #1859's VRAM budget): 422 passed, 33 skipped, 2 failed, both outside this PR: `test_vram_budget_row.py` (fails the same on main's own sources here) and `test_portable_builder_startup.py` (its `dotnet publish` needs packages this PC does not have). A build of the branch compiles. All 81 of main's rows keep main's definitions word for word; the only additions are the six headings. `test_menu_sections.py` fails on main as it stands (no sections) and passes here; a layout with a section of Reflex and Anti-Lag 2 alone fails it. - A build of this branch (Windows 11, RTX 5090), headless with scripted menu keys at Small, Medium and Large: 12 Downs from the Quality preset land on V-Sync and 13 Ups come back past it to the last row, so every heading is stepped over both ways and Up from the first row wraps to the last; the help box always shows the selected row (at the first head, when Robust buffers was the last row). Again at this head (25feb16, after #2042, #1859 and #2119): Up from the Quality preset wraps to Mesh shaders, the last row now, under VRAM budget (the bottom screenshot). **Not tested**: in a window with a pad, the mouse wheel and a click just under a heading (the headless runs drive the keys); values kept across a restart (no row's saved key changes); AMD and Intel (their rows hide through `row_shown` as before; the new check makes sure no section can end up empty), Linux. **Screenshots** The Graphics tab at 1920x1080, Medium menu size: the top, then scrolled with the keys to V-Sync and to the last row (the selection steps over every heading; Up from the first row wraps to the last row). The bottom one is retaken at this head (25feb16, a 16:9 picture: `HOS_ASPECT=1.7778`, as on a 16:9 monitor); the others are from the first head (634ef65). 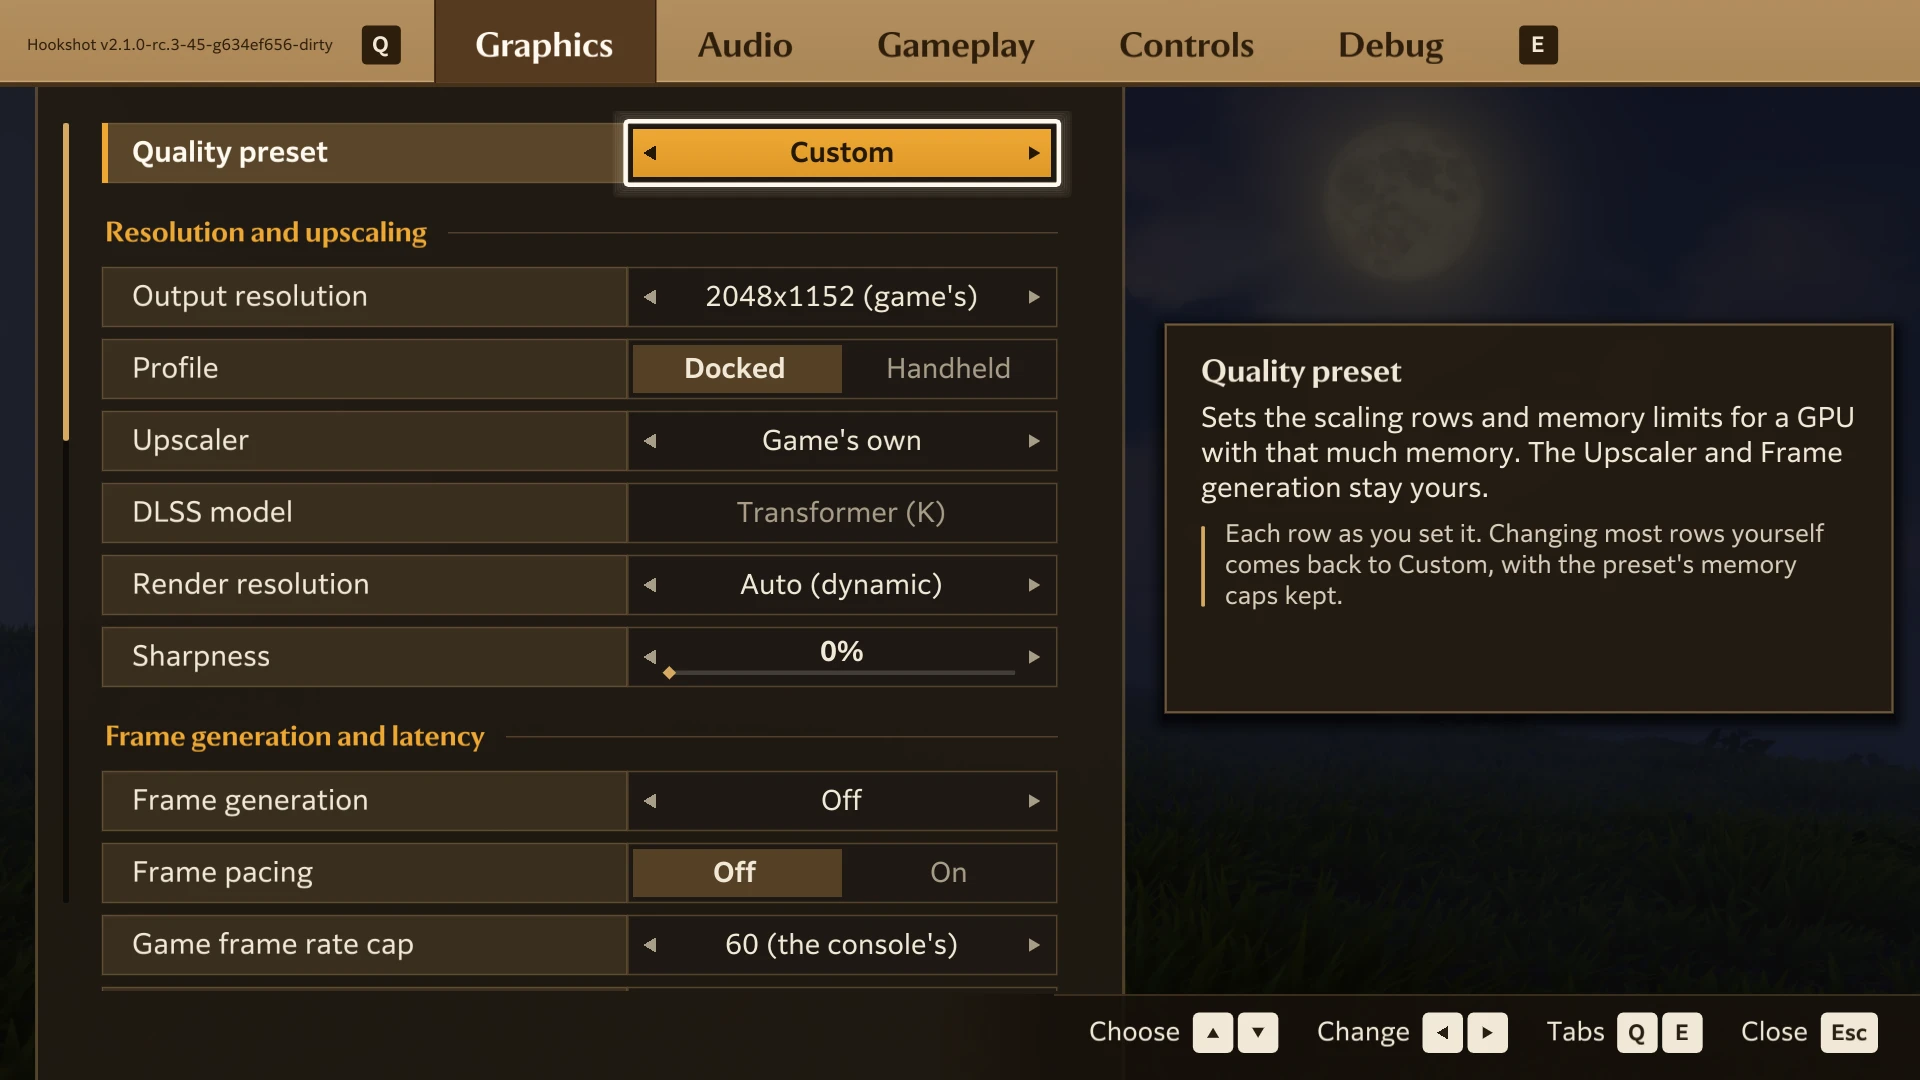 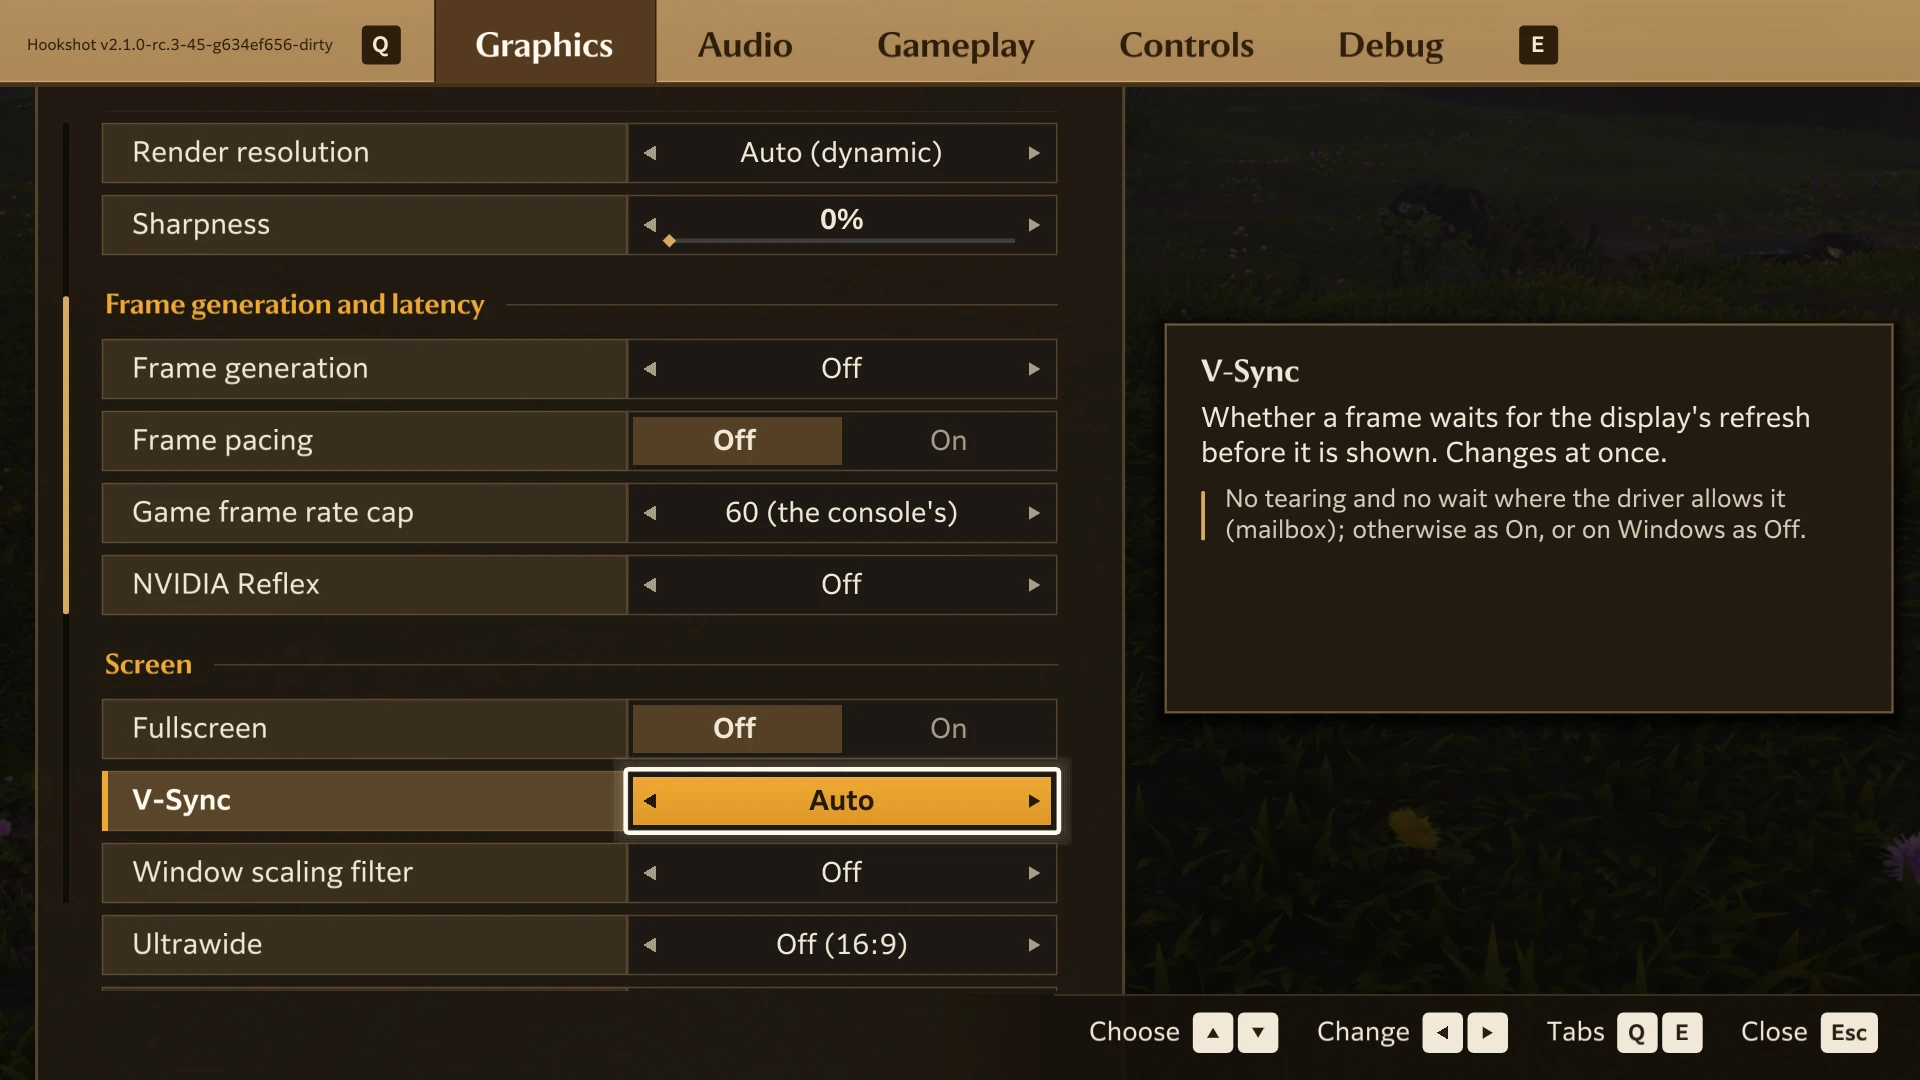 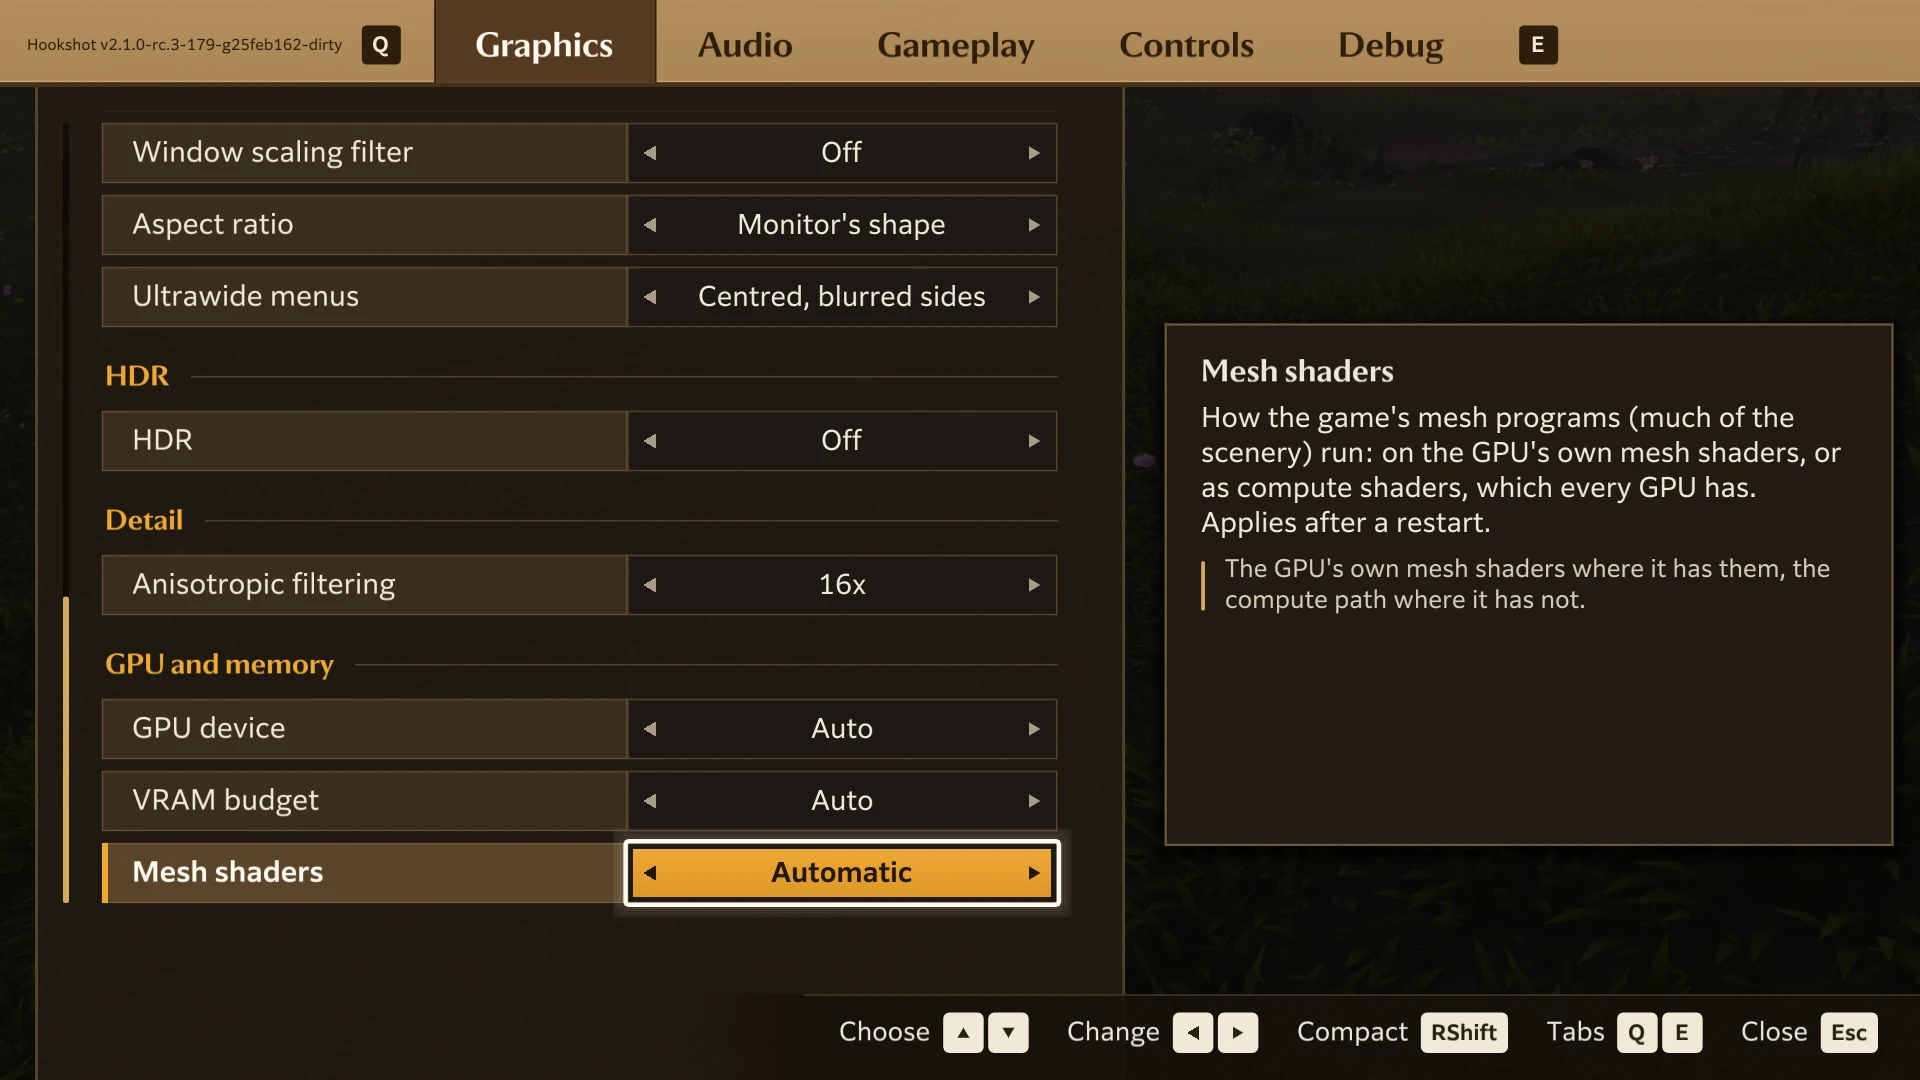 Small and Large: 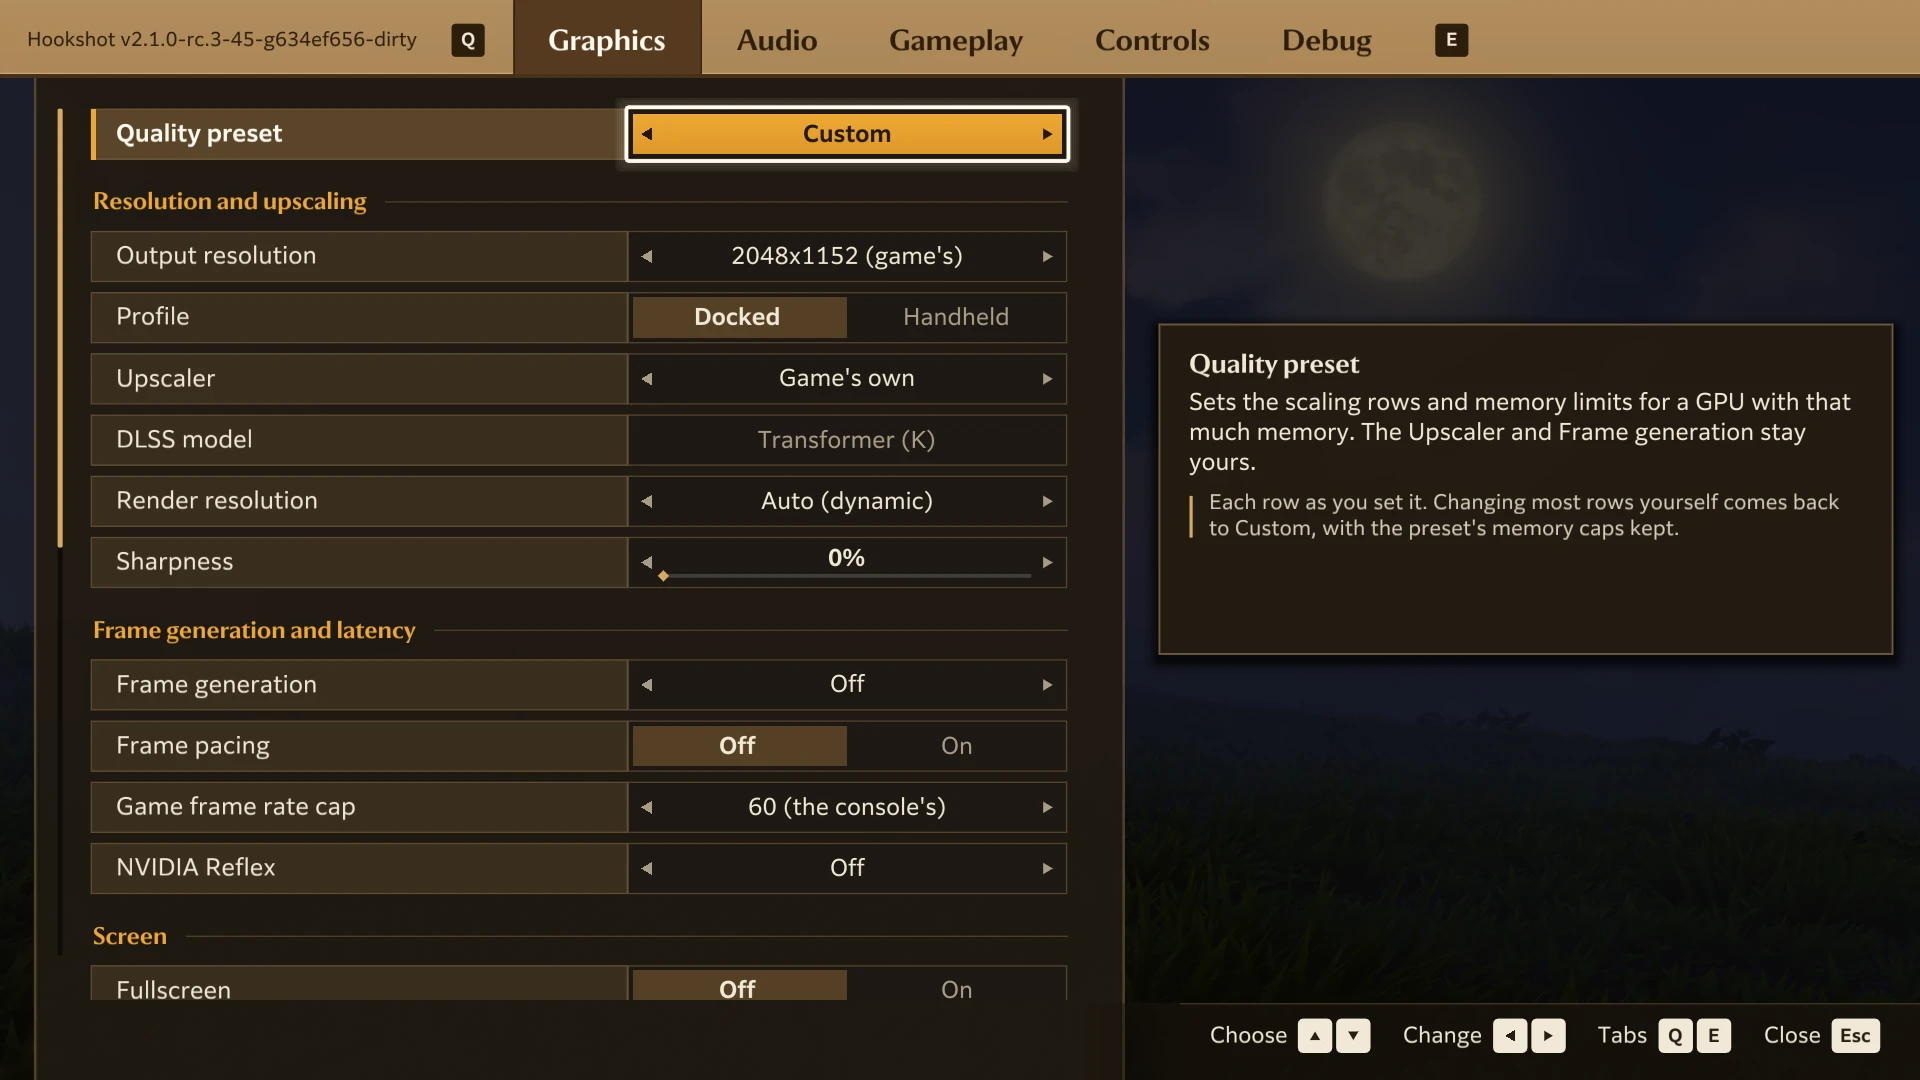 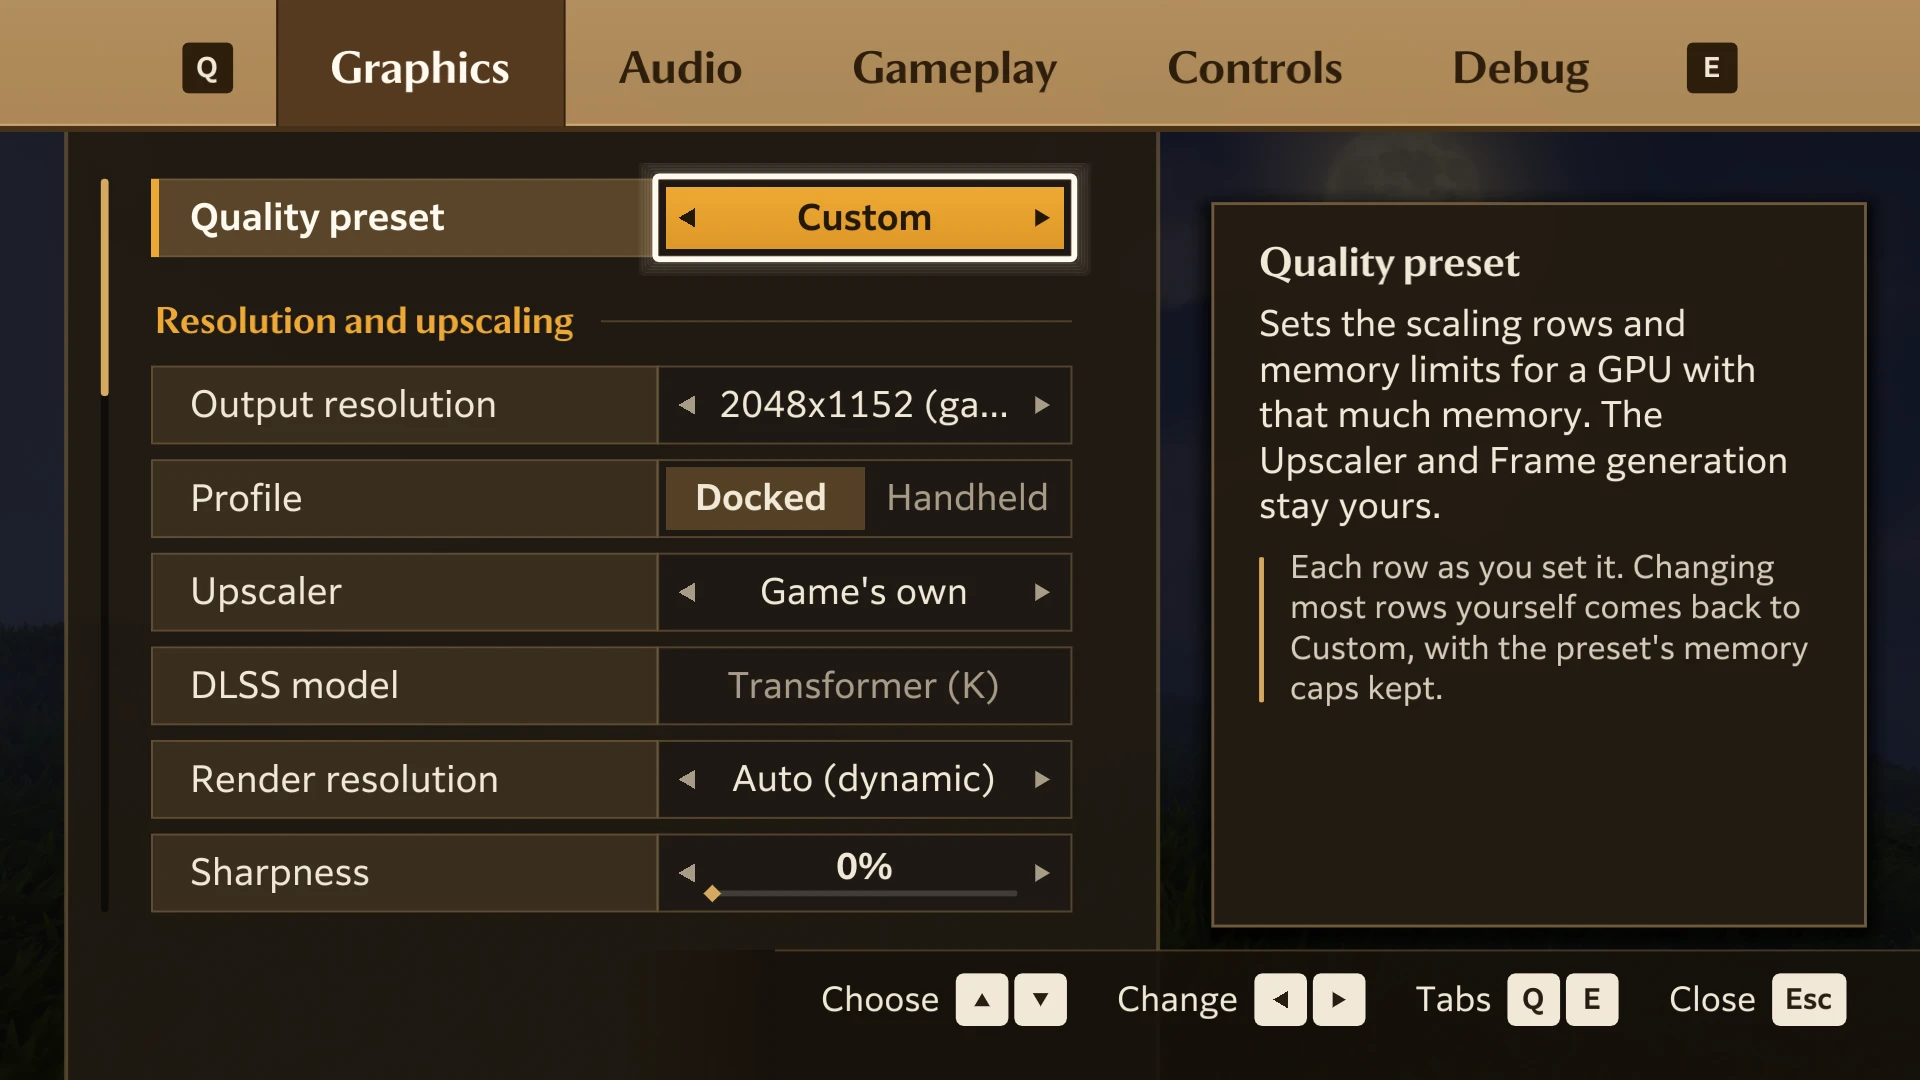 _Taken from headless runs of this branch (`HOS_HEADLESS=1`, `RX_VK_SHOT_MENU=1`, the keys from `RX_VK_MENU_SCRIPT`), RTX 5090. Headless, the list never scrolls on main either: `menu_record_image` leaves `ease_step` at 0, so the build behind the scrolled shots had one more line there (`ease_step = 1.0f`, hence "-dirty" in the first head's build label), not part of this PR. The windowed menu eases as before._ 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
… its GPU work belongs to (#2499)

Follows @nullifyshot's lead on #2118
([comment](#2118 (comment))).
Under DLSS frame generation, Reflex's own "to the GPU's end" read
243–442 ms there (RTX 5080, 4x), next to ~21 ms from simulation start to
present end. Hookshot chained no `VkLatencySubmissionPresentIdNV` to its
queue submits, so the driver had to guess which frame each submit's GPU
work belongs to. Without frame generation it guesses right. With it, the
display thread's copies and DLSS-G's work sit between the game's frames
and get counted as the next game frame's rendering.

**What changes**

`reflex_submit_id(next, frame)` (vk_reflex.cpp) chains a
`VkLatencySubmissionPresentIdNV` to a `VkSubmitInfo2` (vk.xml:
`structextends="VkSubmitInfo,VkSubmitInfo2"`). It is used at the four
submit sites in vk_replay.cpp:

- **`submit_recording`'s direct submit and the parallel segment jobs'
submit:** the frame being made.
- **A batch (`queue_flush_locked`):** the frame of the batch's first
command buffer, kept in `pend.reflex` when the batch starts.
- **`present_image`'s copy:** the frame it shows, by the same rule as
the present id: the set's game frame (`reflex_present_frame`), no tag
for a made frame, and the frame being made without frame generation.

There is no tag when Reflex is off, when no frame is marked, or when
that present id was presented already (present ids only go up). Each tag
is taken right before its `vkQueueSubmit2`, after any flush, and that
flush tags its own batch. `RX_VK_REFLEX_SUBMIT_IDS=0` leaves the tags
off, for an A/B comparison.

**In game:** RTX 5090, 5120x2160 swapchain, DLAA and DLSS-G 3x at
4416x1864 (600 of 600 presents made by DLSS-G), V-Sync Auto, Reflex On +
Boost, `RX_VK_REFLEX_LOG=1`, Kokiri Forest. Same build both runs; run 2
only adds `RX_VK_REFLEX_SUBMIT_IDS=0`.

| | Simulation start → present end | To the GPU's end | Game fps |
Reports |
|---|---|---|---|---|
| Tags on | 40–51 ms | **46–56 ms** | ~44–47 | 13 |
| Tags off (`RX_VK_REFLEX_SUBMIT_IDS=0`) | 44–59 ms | **425–1060 ms** |
~42–44 | 5 |

With the tags, "to the GPU's end" lands a few ms after present end, the
same pattern as without frame generation (12.1 vs 10.1 ms in
nullifyshot's run), so the driver now paces on real GPU timings. The
tags-off run also felt worse to play. Its simulation-to-present numbers
are a bit higher too, but it was a short run (5 reports), so I wouldn't
read much into that gap yet.

What this doesn't measure: input to screen. @nullifyshot, if you have
time, your `HOS_INPUT_LIVE` method on this head would show what it's
actually worth. The ~⅔ of a game frame that interpolation holds the real
frame back stays as it was; Reflex can't remove that.

**Tests:** `test_reflex_swapchain_lifetime.py` copies `reflex_submit_id`
and gains 8 checks (the frame being made, a kept frame, frame 0, no
frame marked, one already presented, Reflex off, retired before the
lock). `draw_stream_visibility_test.cpp`,
`fsr_image_retirement_test.cpp` and `parallel_init_order_test.cpp` get
stand-ins. `tests/run_all.py` (Windows, llvm-mingw clang++): 391 passed,
31 skipped, 1 failed: `test_vram_budget_row`, which reads only
`vk_menu.cpp`, `vk_menu.h` and `vk_memory.cpp` (not touched here) and
fails the same way on main.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>


Frame generation no longer turns Anti-Lag 2 off. As NVIDIA Reflex's
markers with frame generation (NotRexed#2118), each set keeps the game frame it
was made at (antilag_frame), and only the set's game frame gives that
frame's present stage (antilag_present_frame, kept by a deferred present
until its commit); the made frames' presents give none. Without frame
generation nothing changes. The row's hint takes the Reflex row's
wording and translations.
With frame generation on, AMD Anti-Lag 2 turned itself off, so on AMD
GPUs the input delay that frame generation adds got no help: the menu
row said On, but the log said `vk: AMD Anti-Lag 2: off`. This keeps it
on with frame generation.

Rebased onto main after #2118, and now built the way #2118 gives NVIDIA
Reflex its present markers with frame generation.

## What changed

- `vk_antilag.cpp`: frame generation no longer turns Anti-Lag 2 off. The
input stage is where it was (after the game thread's present, with
Reflex's sleep). The present stage now gives the index of the frame the
present shows, not the latest one: with frame generation, the display
thread shows a frame after the game thread has already given the next
frame's input stage.
- `vk_antilag.h`: `antilag_present_frame`, a `thread_local` like
`reflex_present_frame`: `kAntiLagThisFrame` (the default) is the frame
being made, as without frame generation; the display thread sets a set's
game frame for its game frame and 0 for a made frame. `antilag_frame()`
is the frame whose input stage was given last, like `reflex_frame()`.
- `vk_framegen.cpp`: each set keeps `antilag_id = antilag_frame()` next
to `reflex_id` in `framegen_record`, and `display_main` sets
`antilag_present_frame` with the same choice as `reflex_present_frame`
(`timed ? game[k] : k == made`) in both the direct path and present
ahead. So only the set's game frame gives the present stage, at the same
present that gets Reflex's present id and markers; the made frames
before it give none. Auto, fixed 2x and up, FSR 3.1 interpolation and
DLSS frame generation all go through this path.
- `vk_replay.cpp` / `vk_framegen.h`: a deferred present keeps it in
`PendingPresent::antilag_frame`, and `present_commit` restores it around
`present_out`, as it does for `reflex_frame`. `present_out` still gives
the stage right before `vkQueuePresentKHR` (and before a hand-off to the
present thread). Without frame generation nothing changes.
- A frame from before the row was last turned on gets no present stage
(its input stage went to the driver's earlier run).
- The row's hint now reads like the Reflex row's ("With frame generation
too: it paces the game's frames."), and its 13 translations take the
Reflex row's second sentence in each language. The README line says it
works with frame generation.

## How it was tested

- `tests/test_antilag.py` compiles the real functions against the Vulkan
headers with a recording `vkAntiLagUpdateAMD`. It checks the stages
without frame generation, a game frame's present stage given after the
next frame's input stage with its own index, nothing for a made frame
(0), nothing for a frame from before the row was turned on again, and
Off told once. Its wiring checks cover `framegen_record`, both present
paths in `display_main`, the deferred present in `present_image` and
`present_commit`. It fails on `main`.
- The present-semaphores and present-source-crop fixtures got the new
field and stub.
- `python -I -B tests/run_all.py`: 448 passed, 37 skipped, 10 failed on
Windows. The same 10 fail on unmodified `main` on this PC (builder,
portable, updater and a few local-environment checks), not from this
change.
- `vk_antilag.cpp`, `vk_framegen.cpp`, `vk_replay.cpp` and `vk_menu.cpp`
compile with llvm-mingw against Vulkan-Headers v1.4.345.
- In the game, the rebased version (main + this PR, built from source):
RX 9070 XT, Adrenalin 26.10.2, Windows 11, Ryzen 9 3900X, 2560x1440
fullscreen, FSR 3.1, frame generation Auto (144 Hz, present ahead).
About 10 minutes with the row switched off and on several times:
Anti-Lag 2 stays on with frame generation (`vk: AMD Anti-Lag 2: on`, no
`off` after it), each switch took effect at once, 0 late frames (28,652
shown on time in the longest stretch with it on), about 58-59 fps with
it on and off, no hang, no failed submit. The FPS counter's Breakdown
shows more "Pacing" with the row on than off at the same frame time (it
varies from frame to frame): the driver's wait at the input stage now
happens with frame generation too.
- Before the rebase (v2.1.0 base, the present stage then at each set's
first present), the same setup ran about 5 minutes: 41,769 frames on
time, 0 late, no hang.

## Not tested

- Latency in milliseconds: no PresentMon or AMD overlay numbers yet,
only the Breakdown's Pacing above.
- Fixed 2x/3x and up were not run separately (the same display-thread
path as Auto).
- DLSS frame generation (NVIDIA only), Linux / RADV, other AMD GPUs.









On an RTX 5090 at 5120x2160 the built-in frame generation couldn't follow motion. Its block search covers ±32 px per game frame, so a camera pan's vectors fell to zero and every made frame was a cross-fade of two game frames: smoother counters, same stepping motion. This PR makes those frames with NVIDIA's DLSS Frame Generation through NGX, from the temporal upscaler's own depth and motion. It also fixes two pacing problems that made 3x feel uneven even once the frames were right.
What changed (five commits, each on its own)
fix(vk): present 3x and 4x sets ahead too. Frame generation 2x: frames reach the screen 5.7 / 11 ms apart instead of 8.3 (VRR flicker), with cause and a patch #1702's present-ahead (a set's copies go to the GPU together, and only the presents wait for their times) ran for 2x only. At 3x and 4x each made frame's copy still queued behind the game's next frame and reached the screen unevenly. It now runs for any paced set the swapchain can hold, and at 3x/4x the swapchain asks for one spare image per frame (5 and 6 images on NVIDIA).feat(dlss): DLSS-G through NGX (vk_dlss.cpp, beside DLSS on the same NGX session, no Streamline):nvngx_dlssg.dllis looked for where DLSS's runtime is.RX_VK_DLSS_FG=0/1overrides it for a run.fix(vk): V-Sync Auto presents FIFO with DLSS Frame Generation at 2x and up. Auto was mailbox, which on NVIDIA is Fast Sync: below the refresh rate (~135 shown on 165 Hz) frames land on the refresh grid, so evenly timed presents still judder. With DLSS-G making the sets, Auto now asks for FIFO, which a VRR display shows as presented. The built-in frame generation and other GPUs keep Auto as before (from review, item 5). On and Off are unchanged. The swapchain is rebuilt when this changes, as it already is for V-Sync.feat(vk): NVIDIA Reflex with frame generation (added after review). Reflex was off whenever frame generation was on, so its held-back frame added its whole delay (nullifyshot measured +12 to +18 ms at 4x on an RTX 5080). The game's frame calls stay on: the sleep, the simulation markers and render submission. Each set keeps the game frame it was made at, and only that frame is presented with its present id and present markers; made frames get neither. Present ids only go up. Without frame generation nothing changes. On the 5090 at 3x, Reflex's own timings now appear under DLSS-G: simulation start to present end ~41 ms, against ~16 ms with frame generation off (details in the comments).fix(dlss): DLSS-G only where it runs (from review). NGX isn't asked for frame generation's device extensions, or started at a present, on a device without NVIDIA's extensions. V-Sync Auto's FIFO is for DLSS-G only. Frame generation at Off or Auto lets DLSS-G's feature go. A barrier follows a refused frame before the built-in passes write the same images.How it was tested
tests/run_all.py(Windows, at 90c4683): 340 passed, 28 skipped, 3 failed. The same 3 also fail on untouched main at this branch's base here:test_recorder_sync's exit case;test_precompile_compute_guard;test_finish_output(aNameErrorinmake_game.py; it passes on current main).test_present_ahead.py: 3x/4x with and without enough spare images.test_vsync_row.py: the present-mode choice with DLSS-G and with the built-in frame generation.test_upscaler_rows.py: the new row order.present_source_crop_test.cppandtest_present_semaphores.py: stubs for the new calls.test_recorder_sync.py: knows NGX's DLSS-G create/evaluate calls as direct recordings with their B_DIRECT boundary.Not tested / known
VkLatencySubmissionPresentIdNVshould fix it; I'll do that as its own PR.🤖 Generated with Claude Code