


English | 中文
Inspect, clean, transform and ship LLM training data from one CLI; dt view is the interactive entry point.
A training file's row is not a row: it is a conversation, a preference pair, an instruction. Most tools see opaque JSON; dtflow sees the sample, and everything follows from that — a terminal browser that renders samples by their detected format, ~30 pipeable commands that filter on conversation structure, conversion and framework export with lineage, and an agent that can drive all of it.
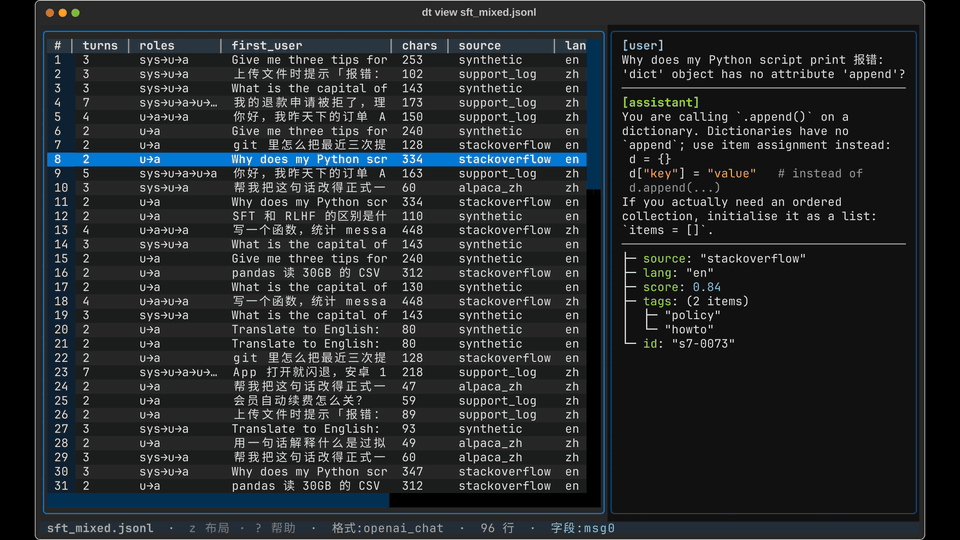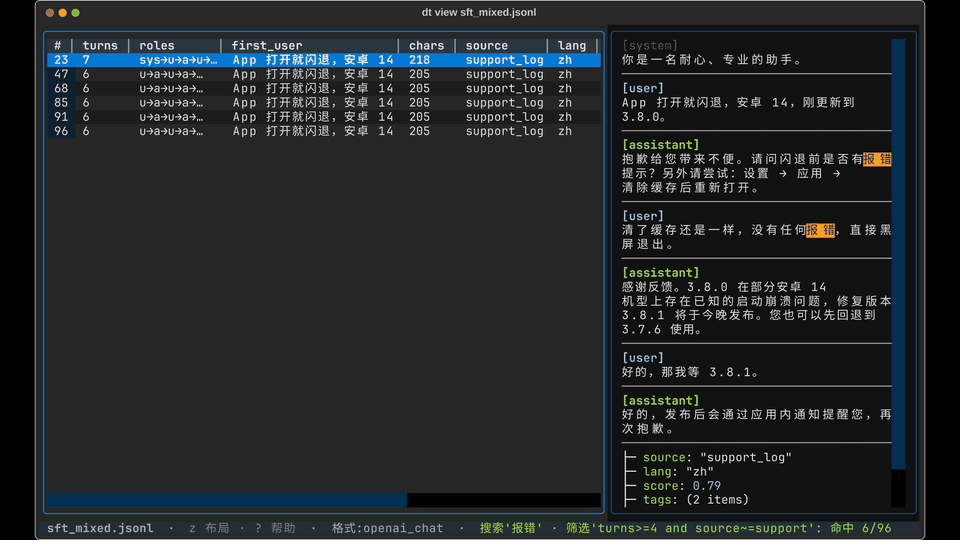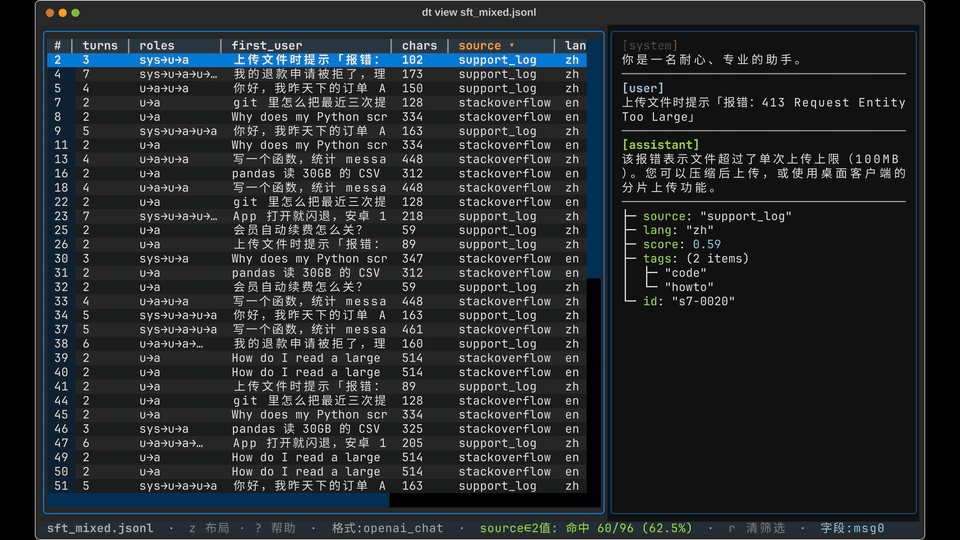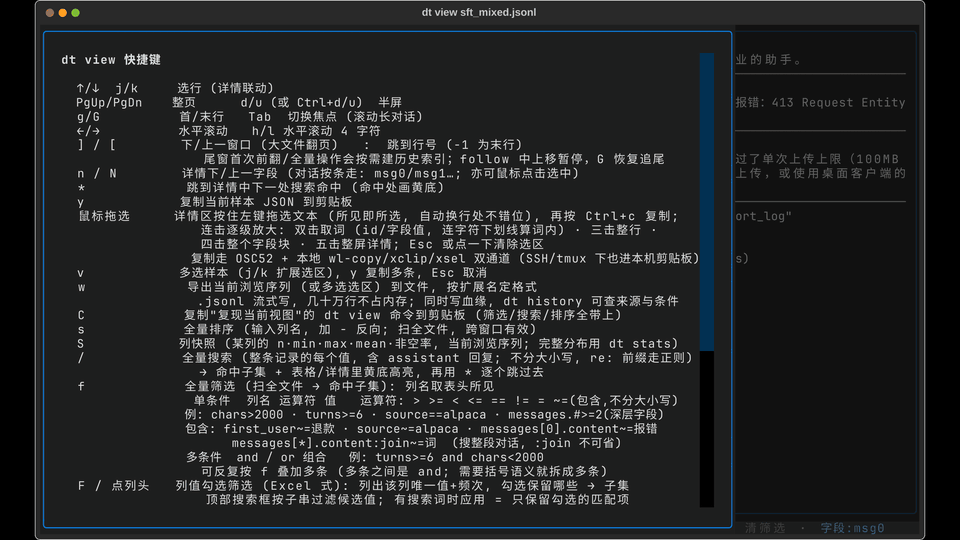
dt view data.jsonl — one screen, one complete sample. Press P and what you just did becomes a dt filter … \| dt sort … pipeline.
pip install dtflow                      # or, without installing: uvx --from dtflow dt view data.jsonl

dt view data.jsonl                                              # browse (press ? for keys)
dt stats data.jsonl --schema                                    # nested schema: types, null rates, values
dt filter data.jsonl "turns(x) >= 2 and search(x, 'refund')" \
  | dt select - "id,turns=turns(x),last=x.messages[-1].content" \
  | dt sort - --by x.turns --desc | dt head - 5
dt transform data.jsonl --preset=openai_chat -o train.jsonl     # sharegpt / alpaca / dpo → OpenAI messages
Reads JSONL/NDJSON (also .gz), JSON, CSV/TSV, Parquet, Arrow and Excel. Every data command accepts - for stdin and writes to stdout when no -o is given, so everything composes. The interface is in English; dt lang zh switches it to Chinese. No data at hand? examples/ has small synthetic chat / ShareGPT / Alpaca / DPO files to try these on.
- It knows what a training sample is. Generic table tools show
messagesas{3}or a truncated string. dtflow detectsopenai_chat/sharegpt/dpo/alpacaand works on the sample everywhere: the viewer renders one complete sample per screen (turns colored by role, tool calls formatted with bad JSON flagged, VLM images one key away), the row helpersturns(x)/roles(x)/calls(x)/search(x, 'refund')filter on conversation structure, presets convert between layouts,token-statssplits tokens by role. - Looking and processing are one loop, in one language. Conditions everywhere are Python with the current row as
x— no DSL, and the viewer compiles the same string asdt filter. The loop closes:Pin the viewer turns what you did intodt filter … | dt sort …;|runs a shell pipe over the whole file with its output browsable right there;wexports the filtered subset with lineage. What you did while browsing becomes a script; a script's output comes back to the viewer withdt … | dt view -. - An agent can drive all of it. stdout carries only data, exit codes are contractual, errors are structured JSON when stderr is not a terminal,
--dry-runpreviews side effects,dt schemaprints the command tree as JSON.dt install-skillinstalls the full reference into Claude Code or Codex — one command, and "clean this dataset" becomes a task your agent can actually do.
Underneath: filter / select / map / clean / dedupe / transform stream and never load the file; a bare field name or an unknown helper is a compile-time error, not an empty result with exit code 0.
Decontaminate — drop training rows that overlap your test set. The join key is a Python expression, so it matches on the first user turn rather than the whole JSON line; rows that differ only in metadata still get caught.
dt join train.jsonl test.jsonl --on "first_user(x)" --anti -o clean.jsonl
dt view clean.jsonl                    # eyeball what survived before training on it
Browse until you understand the data, then turn what you did into a pipeline.
dt view data.jsonl        # / search every value · F tick values to keep · f filter by expression
                          # P copies what you did as:  dt filter … | dt sort …
dt filter data.jsonl "turns(x) >= 4 and x.score > 0.7" | dt view -    # process, then look again
Convert and ship to a training framework.
dt transform shards/ --preset=openai_chat -o sft.jsonl   # a directory works too; sharegpt/alpaca/dpo → messages
dt validate sft.jsonl --preset=openai_chat               # schema check; --filter keeps valid rows only
dt token-stats sft.jsonl --model=gpt-4                   # token distribution per role
dt export sft.jsonl -f llama-factory                     # data + training config template (ms-swift, Axolotl too)
Or hand the whole job to your agent.
dt install-skill # teaches Claude Code (or Codex) the full referenceThen: "drop rows whose last turn isn't the assistant, dedupe by first user message, export for LLaMA-Factory." The agent reads dt schema, previews with --dry-run, and runs the same commands above.
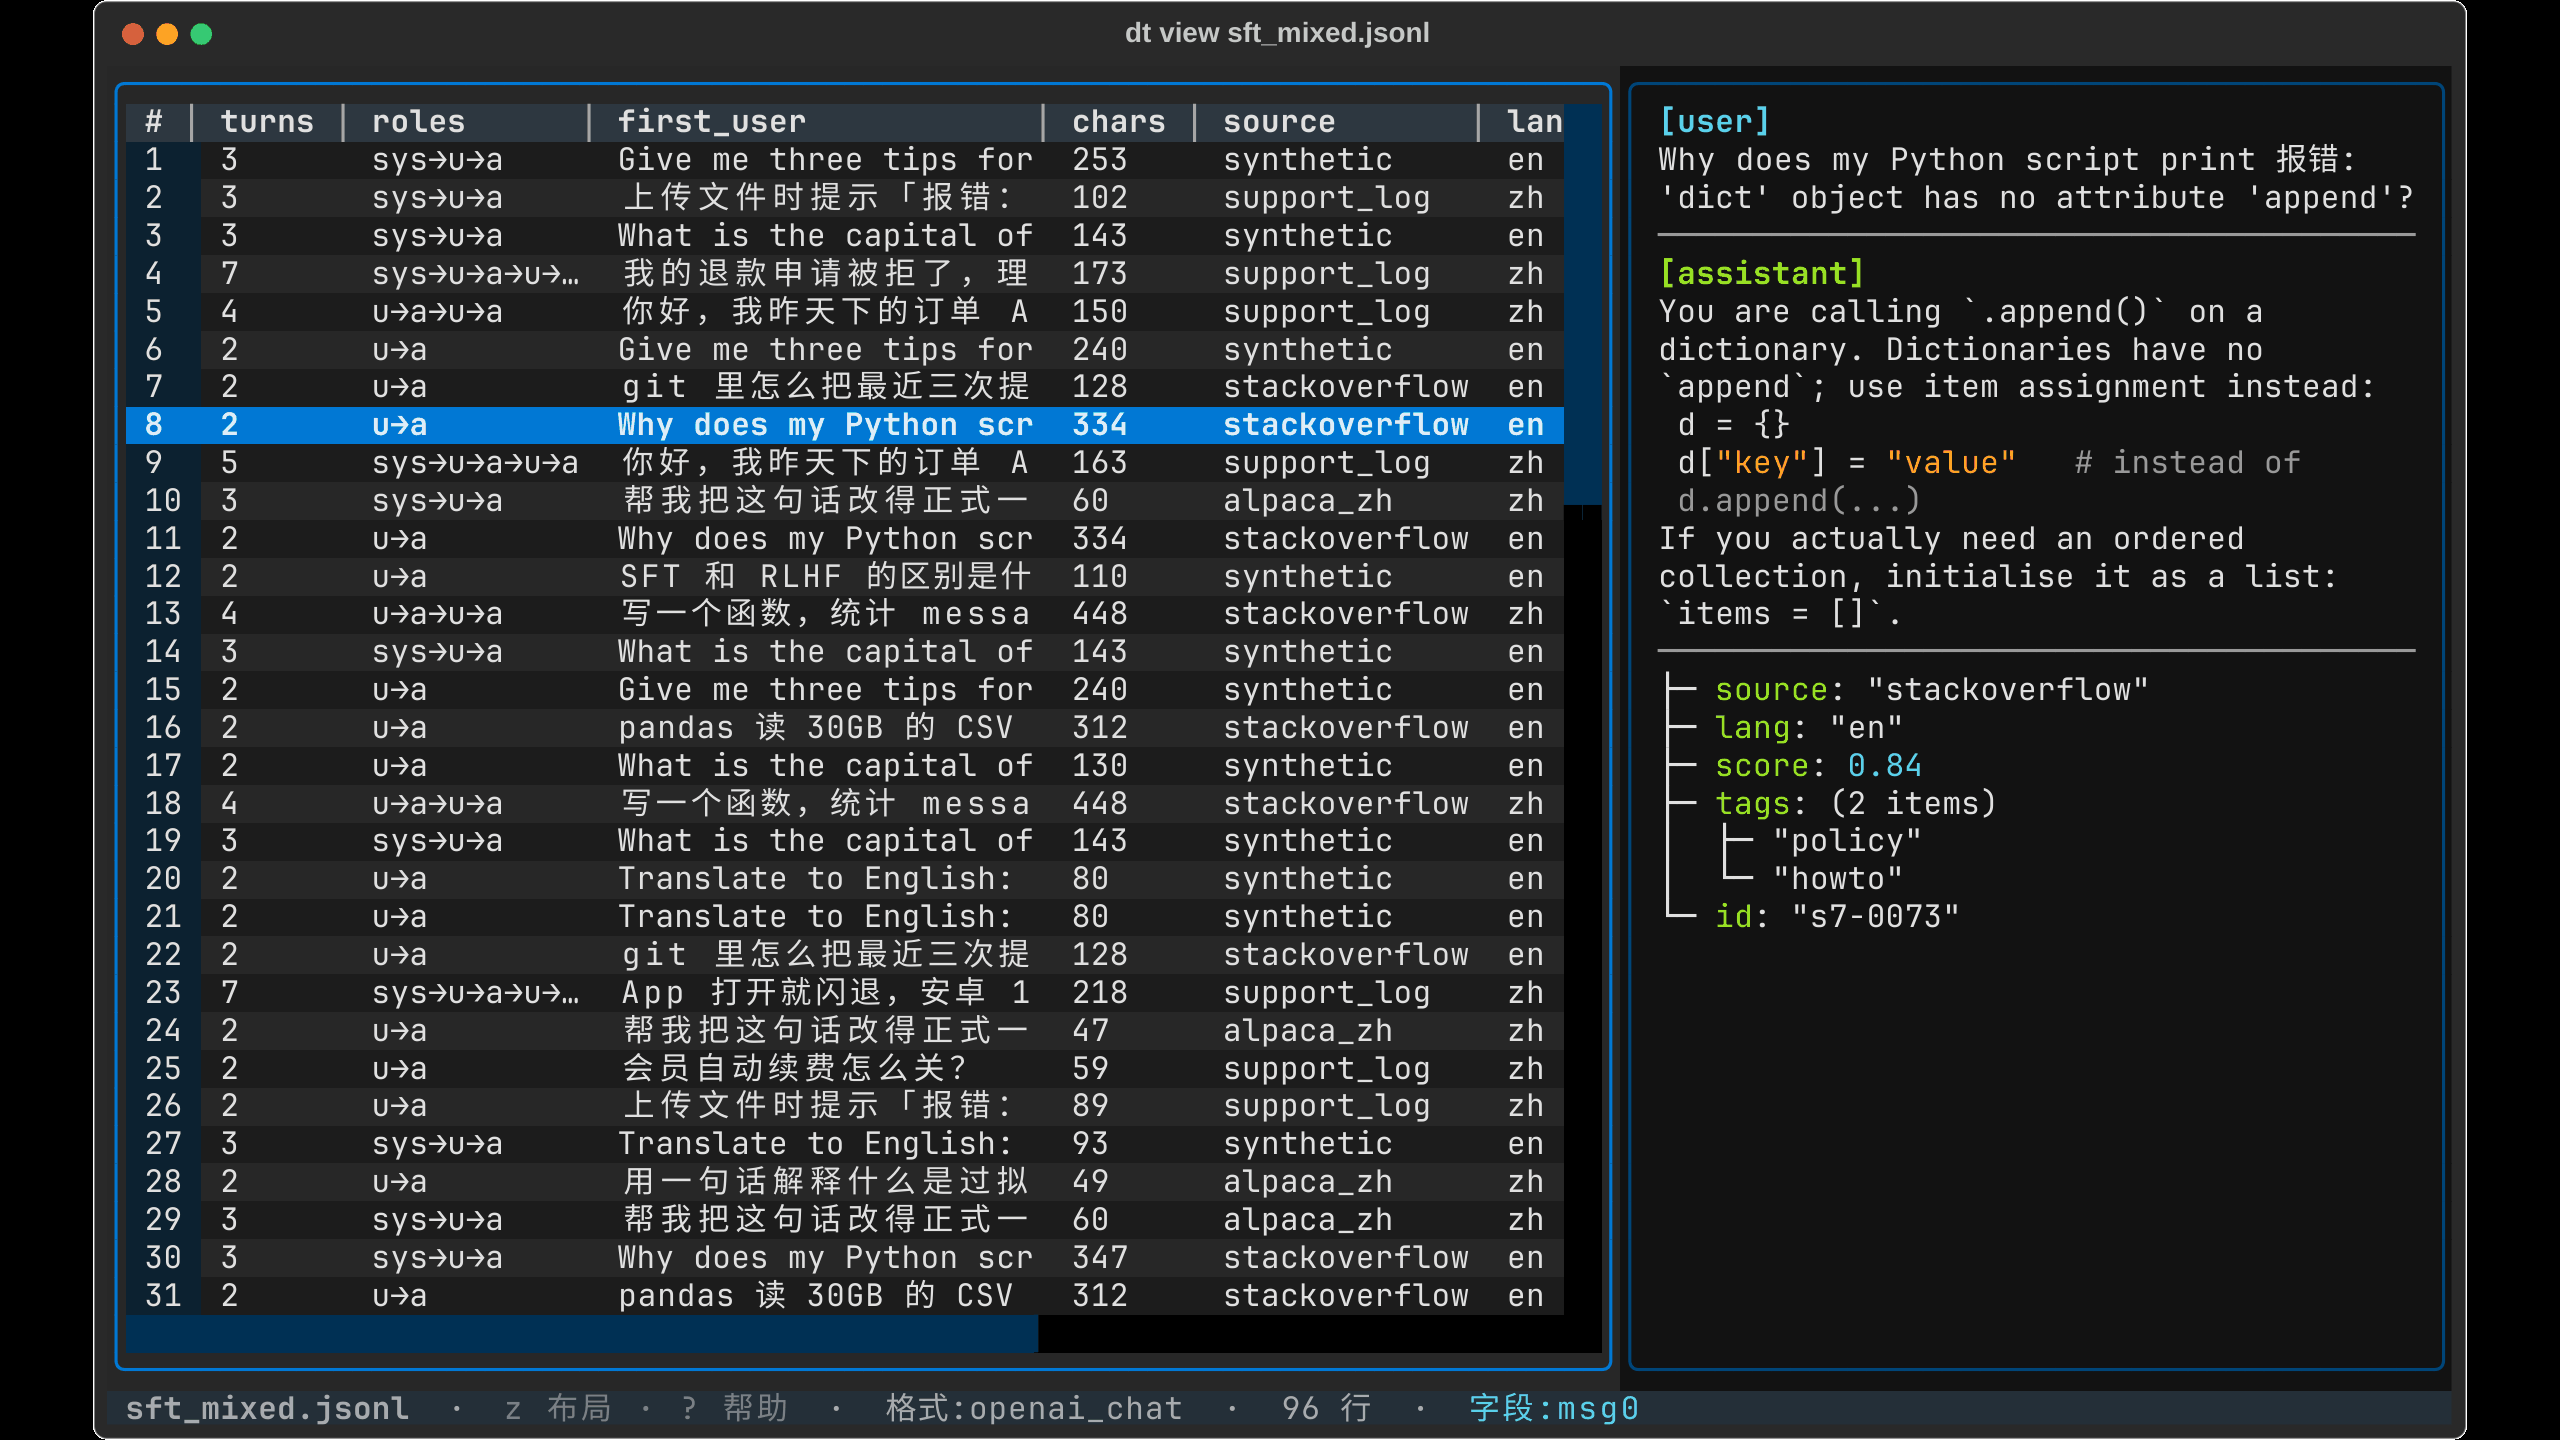
dt view <file> opens a master-detail browser: the table summarizes each sample (derived columns turns/roles/first_user/chars/calls plus your metadata), the detail pane renders the current row by format. JSONL, CSV and Parquet open; a 910k-row file opens instantly at ~90 MB RAM.
 |
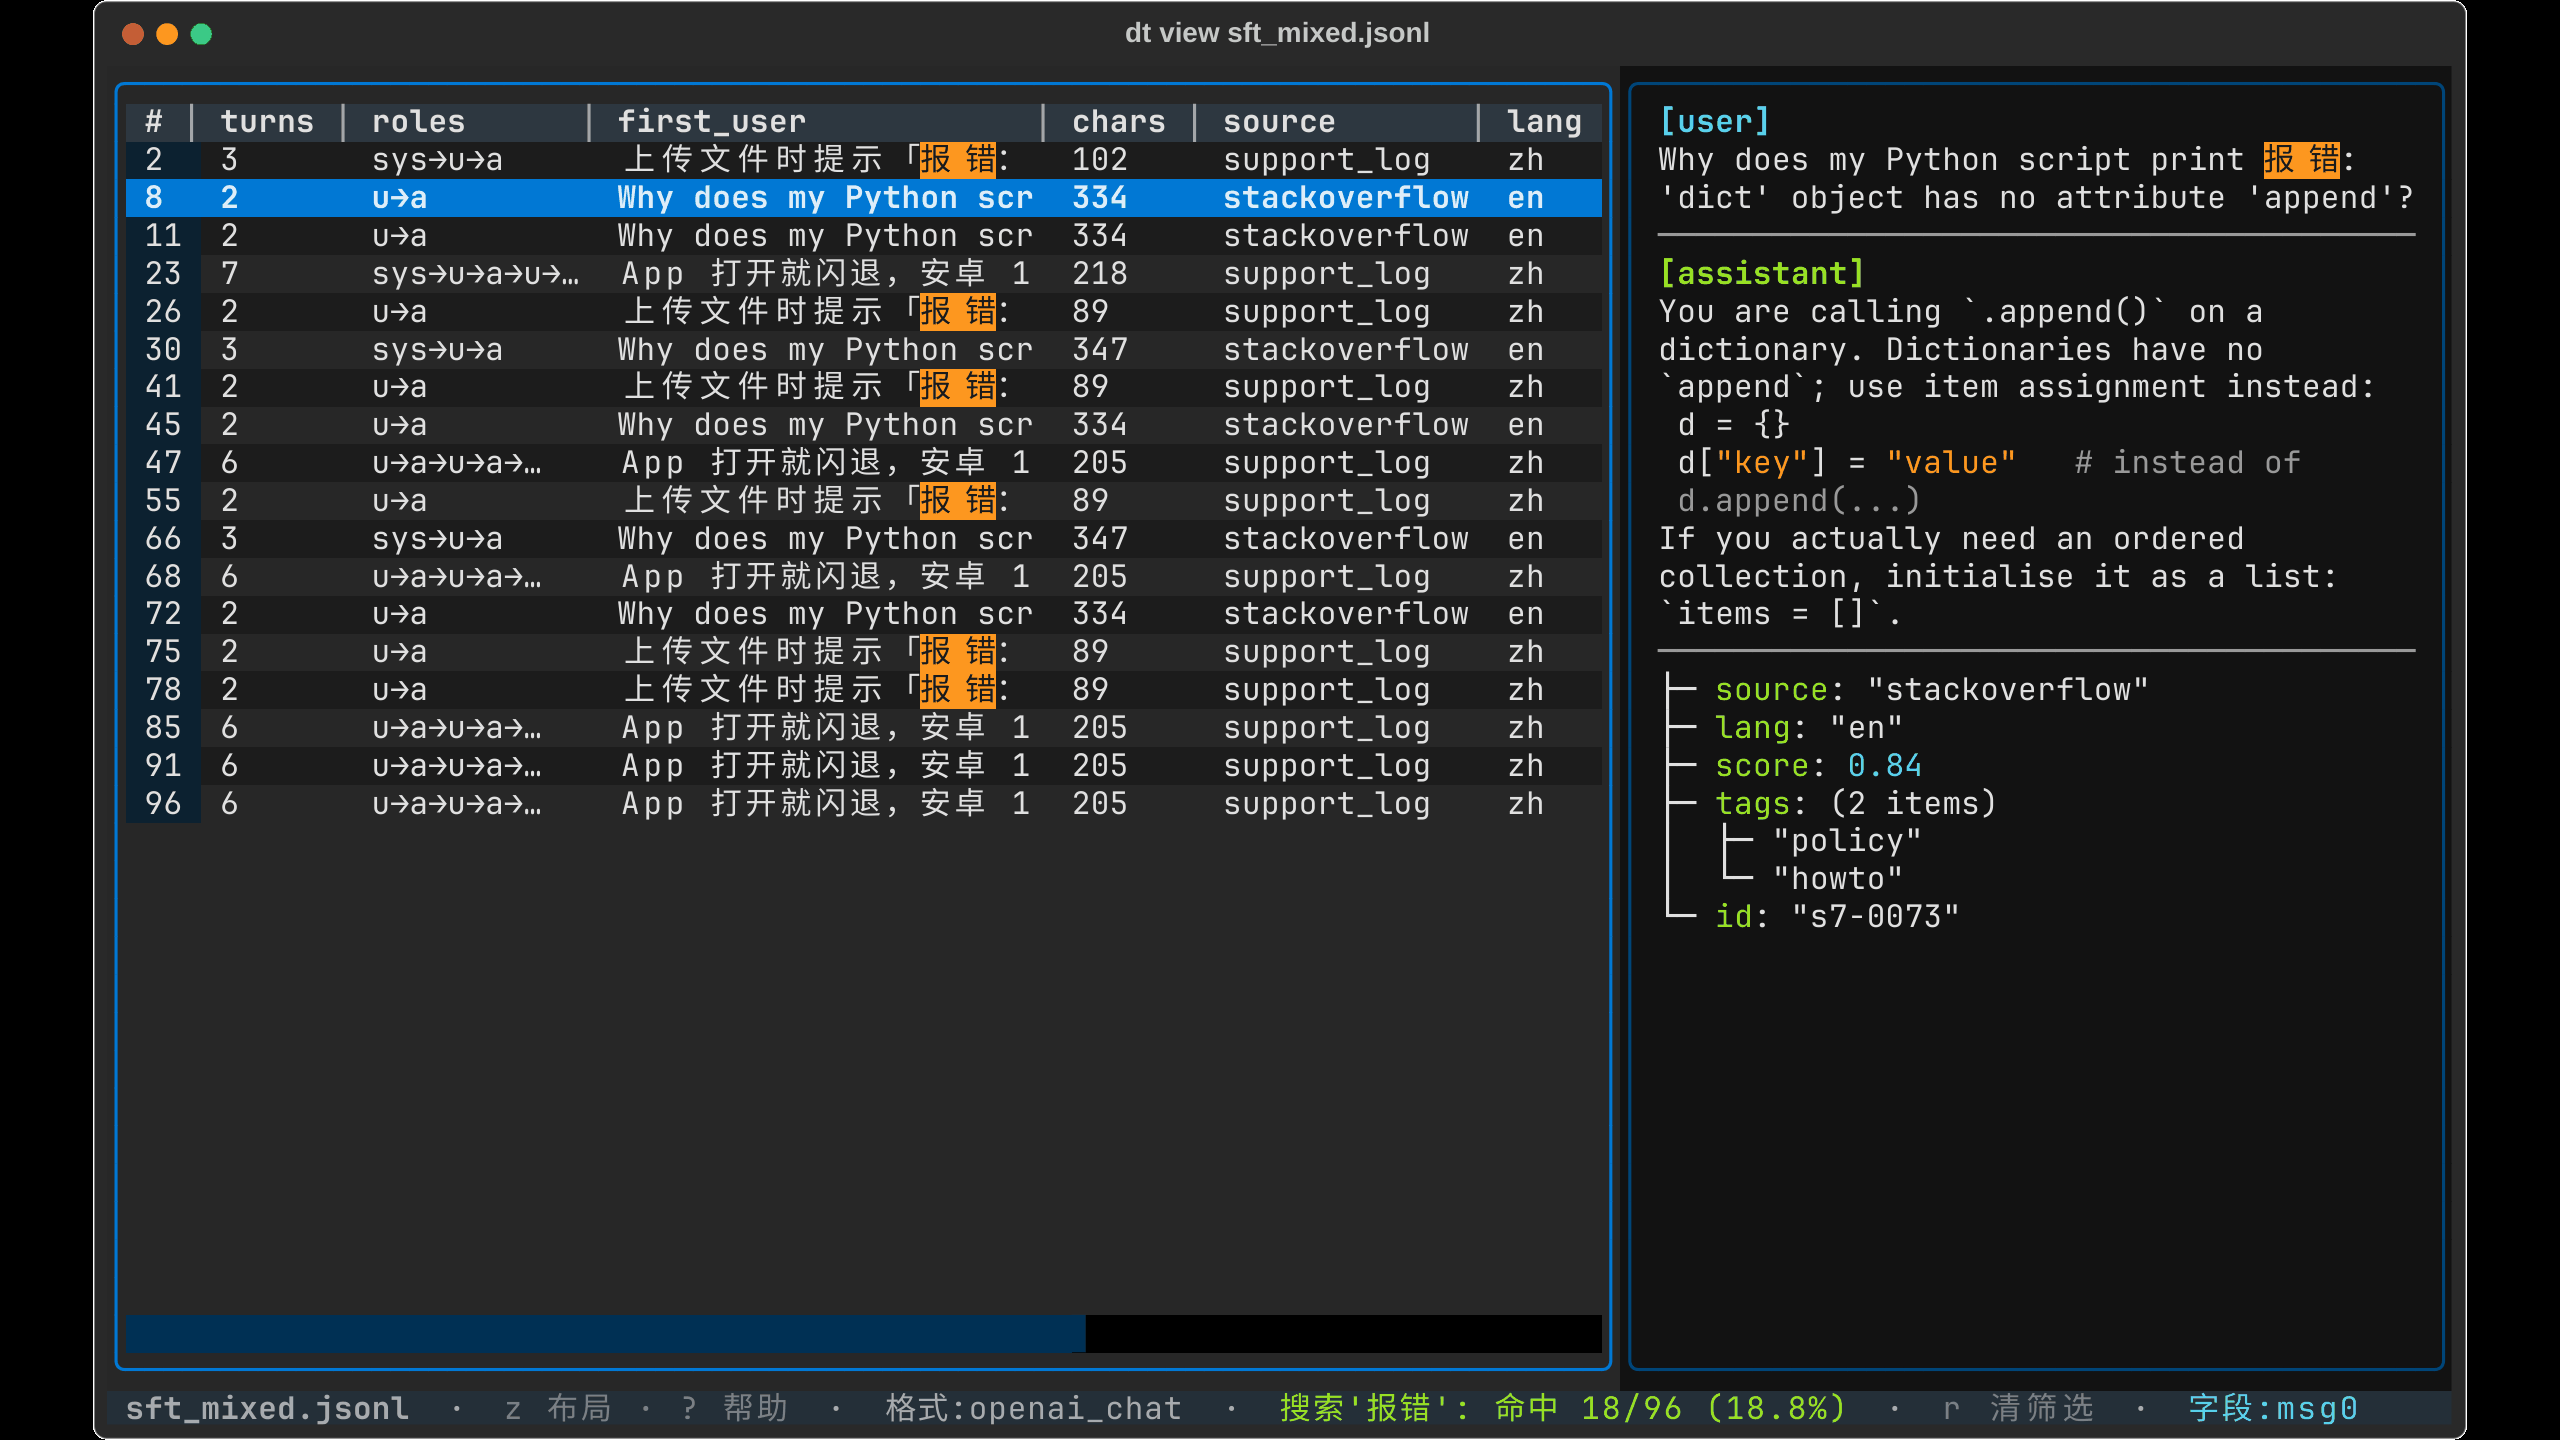 |
| Main screen: pick a row, detail renders by role with code highlighting | / full-file search: every value of every record (assistant replies included), hits in yellow |
 |
 |
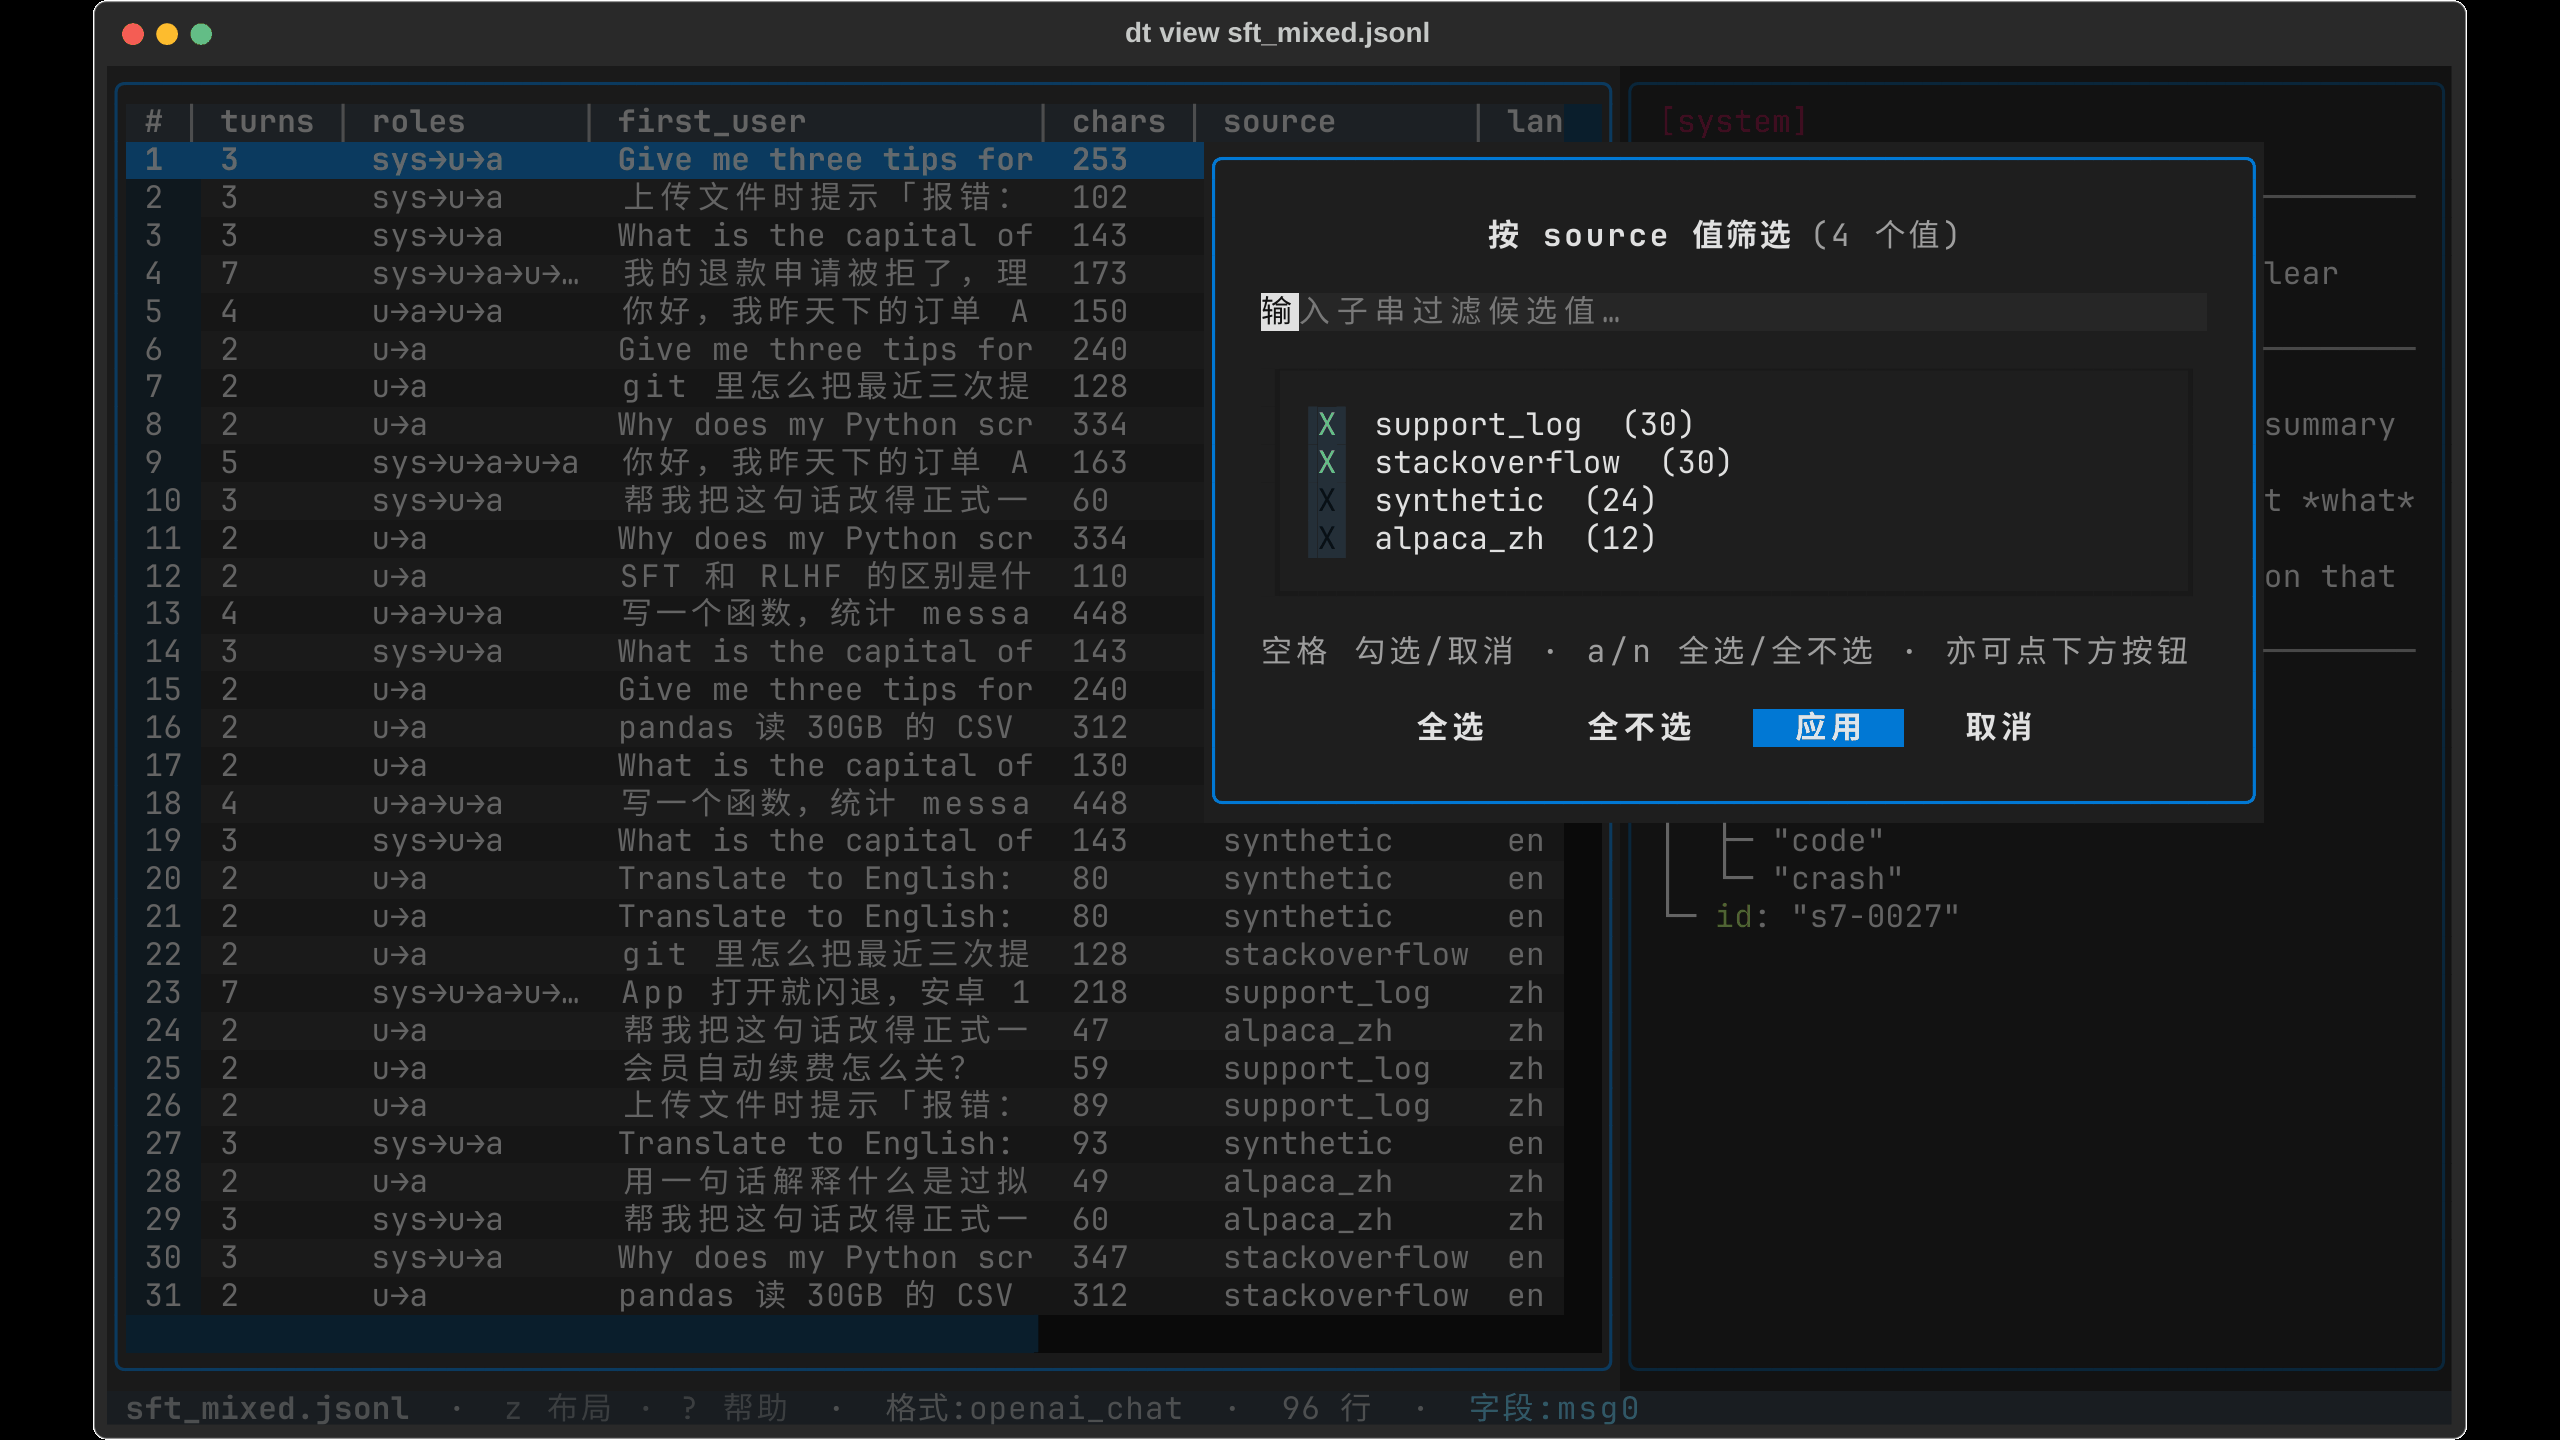
F value picker: Excel AutoFilter style, unique values + counts, keep what you tick |
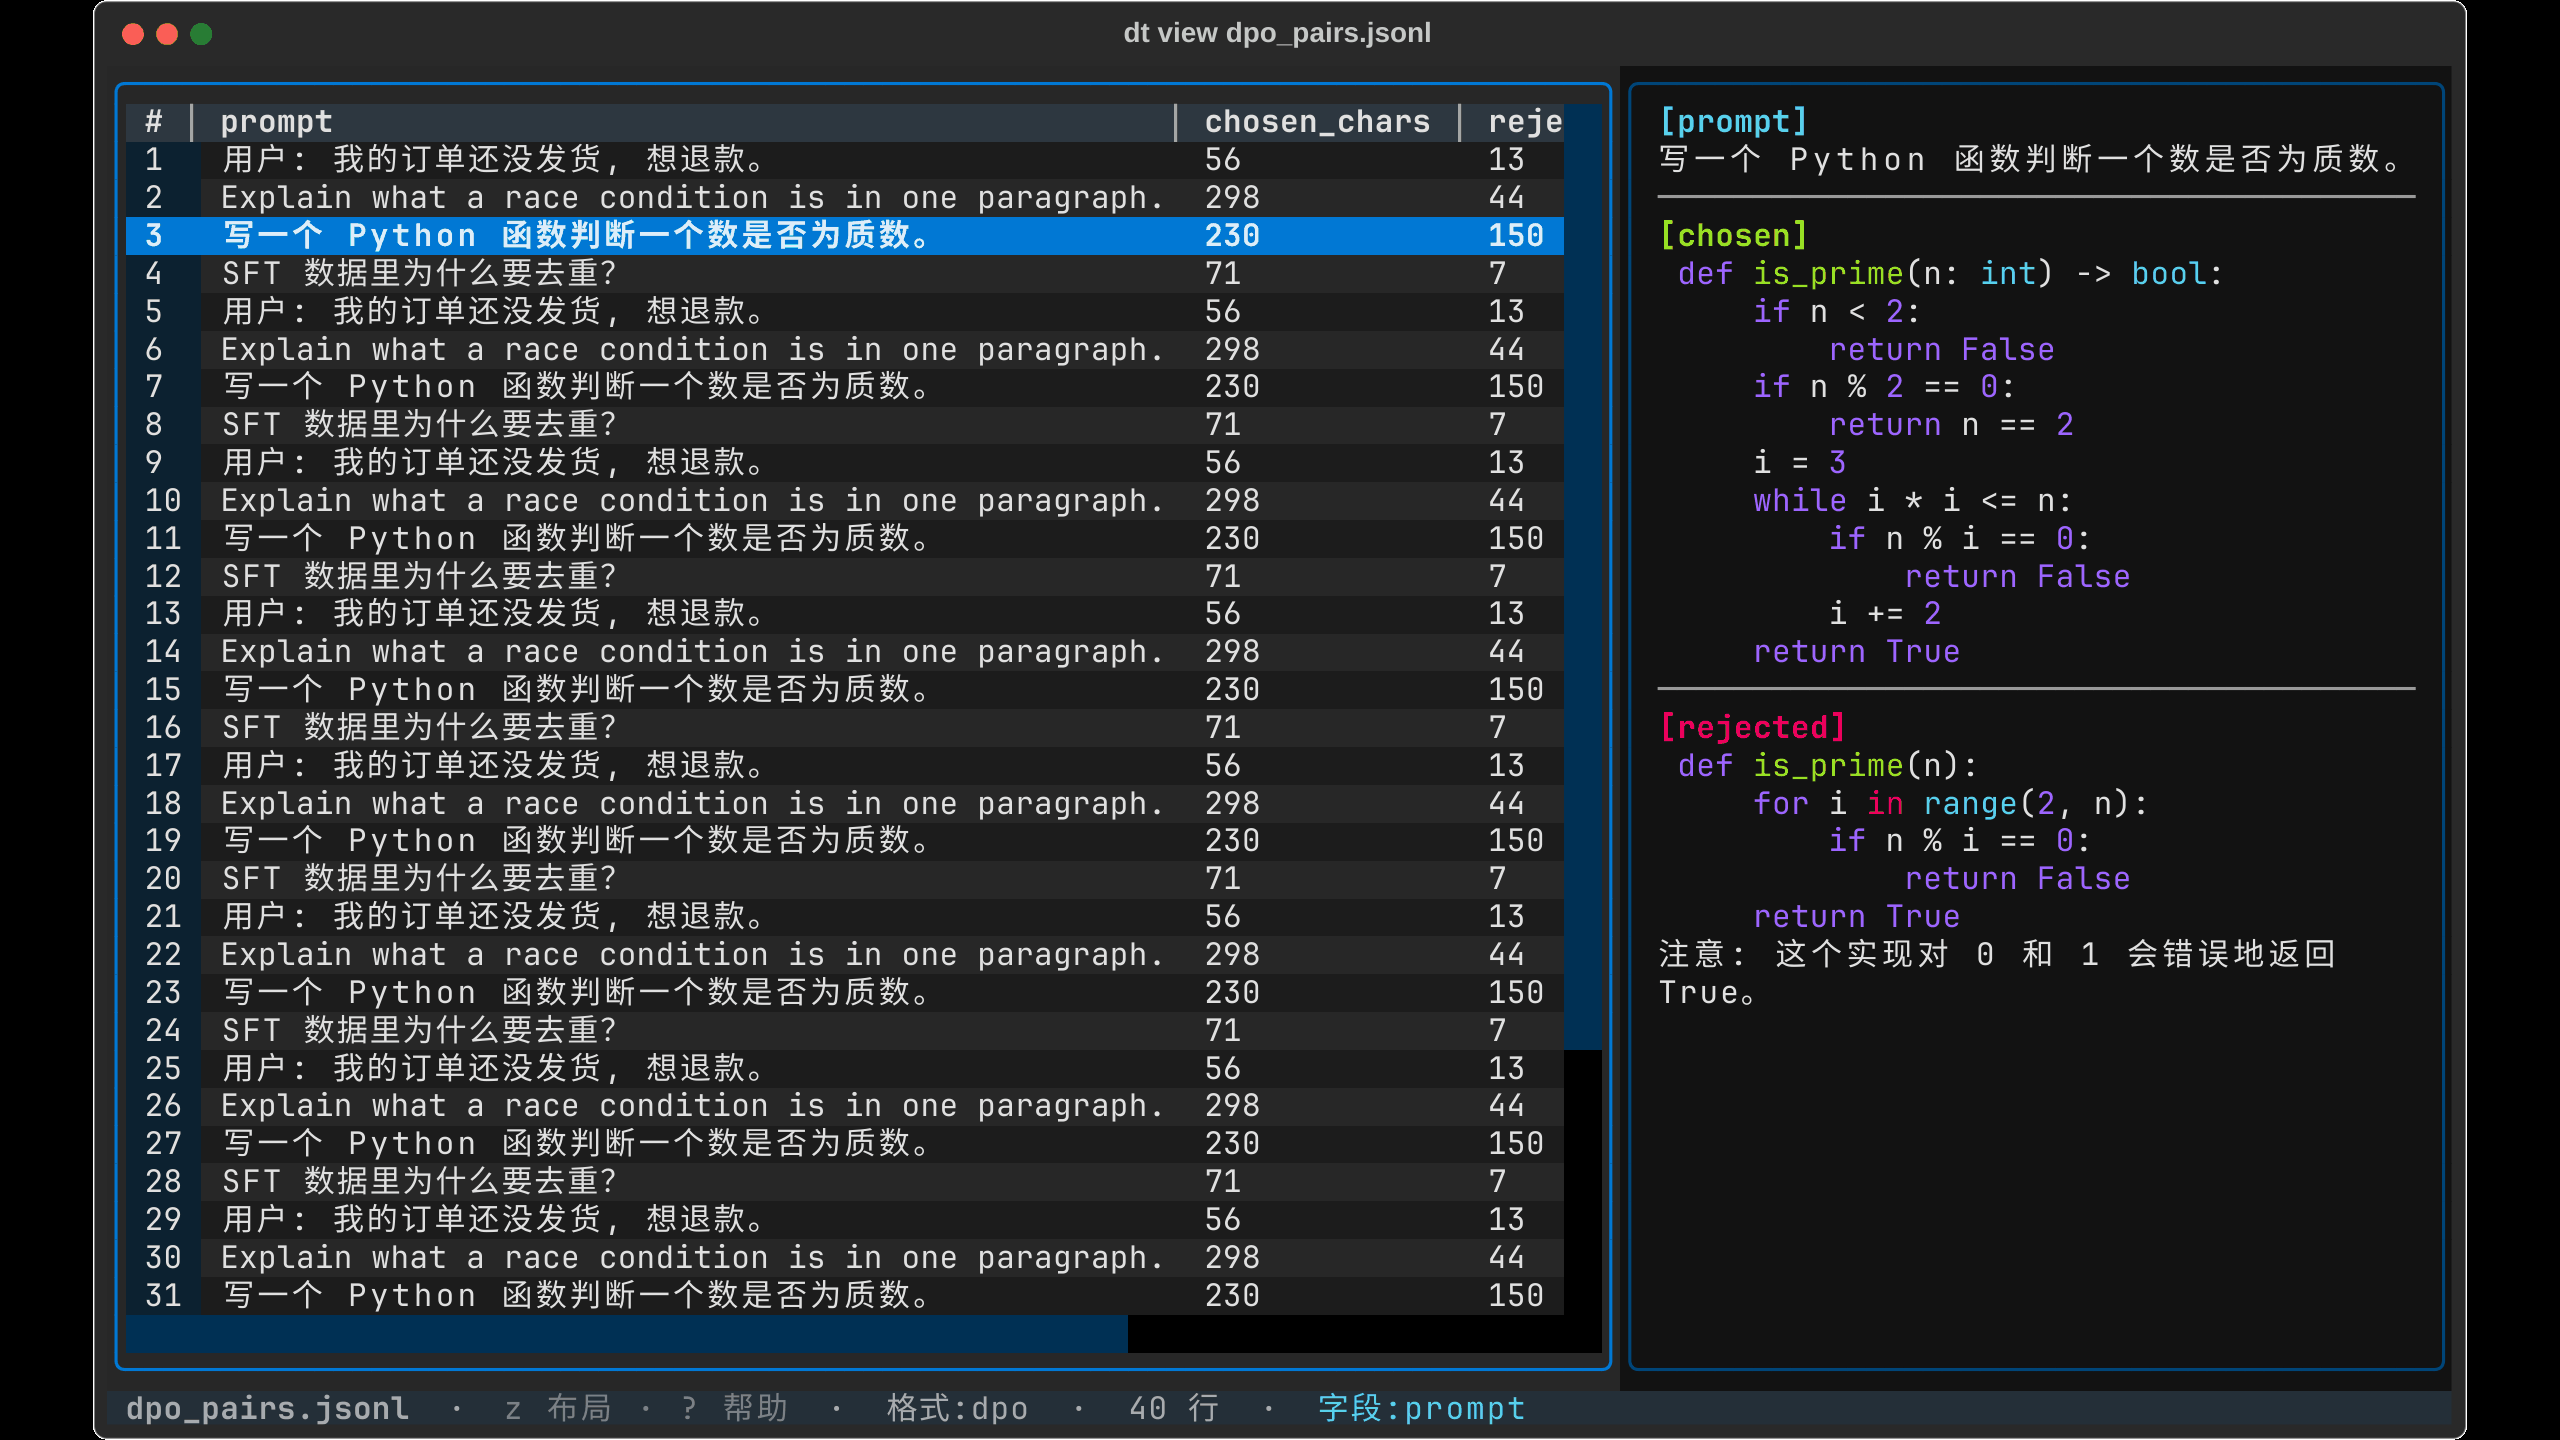
dpo comparison: chosen / rejected in different colors, format auto-detected |
dt view data.jsonl                          # open, press ? for keys
dt view app.jsonl -100 -f                   # follow a growing JSONL (log mode)
dt view data.jsonl -w "turns(x)>=6" -s error   # start filtered + searched
dt sample data.jsonl 500 | dt view - # pipe: inspect sampled / processed output| Keys | What they do |
|---|---|
/ f F |
Full-file search · expression filter (the same Python as dt filter) · Excel-style column value picker. They stack; r clears all |
Enter n/N * |
Zoom into the sample · jump field by field · jump only between search hits |
w C P |
Export the filtered subset (lineage written) · copy a reproducible dt view command · copy the same conditions as dt filter … | dt sort … |
| |
Run a shell pipe (dt filter - … | dt sort - …, jq works too) over the whole file and browse its output right there; r returns to the file |
| mouse | Click a header to open its value picker, drag column widths and the split, drag-select text to copy (over SSH and inside tmux too) |
Against other terminal viewers: VisiData, tabiew, jless, fx and csvlens are generic table/JSON tools — none of them knows what a training sample is, none has mouse filtering, and opening a 155 MB / 910k-line JSONL costs them 550 MB–2.3 GB of RAM against dt view's 91 MB. Where they win (pivots, SQL, deep JSON folding) and the full comparison table: docs/view.md.
Every data command follows one contract: FILE may be - (stdin), a directory or a quoted glob; without -o data goes to stdout while progress goes to stderr; output format follows the extension. Conditions, keys and derived fields are Python expressions with the current row as x.
# look before you touch
dt stats   data.jsonl --schema                        # nested schema: types, null rates, sample values
dt describe data.jsonl "turns(x)" "x.score"           # quantiles + histogram per expression
dt token-stats data.jsonl --model=gpt-4               # token distribution per role
dt diff    a.jsonl b.jsonl --key=id                   # what changed between two versions

# shape
dt select  data.jsonl "id,n=len(x.messages)"          # project / rename / derive
dt map     data.jsonl "x.text = x.text.strip(); del x.debug"   # edit in place
dt explode data.jsonl --field messages --index-as turn         # one row per list element
dt group   data.jsonl --by "roles(x)" --top 10        # {"key","count","pct"}
dt sort    data.jsonl --by "len(x.messages)" --desc
dt sample  data.jsonl 1000 --by=meta.source           # stratified sampling
dt split   data.jsonl --ratio=0.9 --seed=42           # train/test files

# combine & clean
dt dedupe  data.jsonl --key=messages[0].content -i    # exact dedupe, in place
dt clean   data.jsonl --drop-empty=text --min-len=messages.#:2
dt concat  a.jsonl b.jsonl -o merged.parquet          # one file in = format conversion
dt run     pipeline.yaml                              # reproducible pipeline, steps = CLI commands
Rows whose expression fails (missing field, None > 0.5) don't abort the run — filter drops them, select sets the item to null, map keeps the row, and stderr prints one summary at the end; --strict turns the first failure into exit code 1. In a terminal, results preview as a 50-row table with the same columns as dt view; piped, they emit NDJSON.
Command reference: docs/cli.md · expressions and field paths: docs/expressions.md · pipelines: docs/pipeline.md.
The same operations as a chainable class; x.field attribute access works on nested dicts and lists.
from dtflow import DataTransformer, load_stream

(DataTransformer.load("data.jsonl")
    .filter(lambda x: x.score > 0.8)
    .transform(preset="openai_chat", user_field="q", assistant_field="a")
    .dedupe("messages[0].content")
    .save("train.jsonl"))

(load_stream("huge.jsonl")                 # constant memory for files that don't fit
    .filter(lambda x: x["score"] > 0.5)
    .save("filtered.parquet"))
Presets (openai_chat, alpaca, sharegpt, dpo_pair), schema validation, token counting with tiktoken or HuggingFace tokenizers, converters for LLaMA-Factory / ms-swift / Axolotl / HuggingFace datasets / OpenAI Batch, lineage tracking: docs/python-api.md.
dt install-skill                         # Claude Code (default)
dt install-skill --target codex          # Codex
After installing, /dtflow in Claude Code or $dtflow in Codex gives the agent the full reference.
- Quickstart
- CLI reference
dt view- Expressions and field paths (includes the 0.9 migration table)
- Pipelines
- Python API
- Changelog
MIT